It is shown that the instability of RL under TIM is primarily caused by drift: a persistent bias between training and inference engines that accumulates with every training step, and an additive score centering term is derived that stabilizes RL under TIM by canceling drift.
Abstract
Reinforcement learning (RL) of large language models is notoriously sensitive to small differences between training and inference engines, often referred to as the training-inference mismatch (TIM). However, completely eliminating TIM is impractical, as it would come at a major cost to rollout efficiency. In this paper, we show that the instability of RL under TIM is primarily caused by drift: a persistent bias between training and inference engines that accumulates with every training step. We derive an additive"score centering"correction term that stabilizes RL under TIM by canceling drift. When training models from 0.6B to 30B parameters, score centering alone matches or outperforms methods based on importance sampling under quantization, with the gap growing as the mismatch becomes more severe. Because the correction is additive, score centering also composes with importance sampling -- their composition outperforms pure importance-sampling baselines in our staleness experiments.
We study training-inference mismatch in reinforcement learning with verifiable rewards (RLVR) for large language models, where rollouts are sampled by an inference engine while gradients are computed by a training engine, and the two engines assign different probabilities to the same tokens. To account for this discrep...
Tian-Run Yu, Kai-Xiang Zhao, Shang-Zhe Li et al.· 0 citations
Reinforcement learning (RL) is widely used in language-model post-training to maximize rewards assigned to individual model outputs, such as scores from binary verifiers or reward models trained on human feedback. However, applications such as synthetic-data generation, fairness-related constraint satisfaction, and pol...
Sourabh Kulkarni, Ksheeraj Sai Vepuri, B. Demir et al.· 0 citations
Best Practice Critic Optimization (BPCO) is developed, a recipe that combines DPPO, value predictions bounded to the reward range, Monte Carlo value targets, unnormalized policy advantages, and length-adaptive generalized advantage estimation and shows that a carefully designed critic provides a reliable alternative to...
Proximal Policy Optimization (PPO) for large language models typically trains its critic by mean-squared-error (MSE) regression on scalar value targets. Although scalar MSE is statistically valid for estimating the conditional expected return, sparse binary rewards in reinforcement learning with verifiable rewards (RLV...
Zhi-Jian Zhou, Long Li, Xuan Zhang et al.· 2 citations· ⚡2
Reinforcement learning (RL) has become a key technique for improving the reasoning and agentic abilities of large language models (LLMs). Although FP8 quantization can accelerate RL training, maintaining stability throughout an FP8 RL pipeline remains challenging. While previous works have focused on resolving train-in...
Fan Chen, Ziheng Jiang, Zi-Yun Wei et al.· 0 citations
Reinforcement learning with verifiable rewards is typically performed on-policy, keeping training data close to the current policy but limiting learning to trajectories that the policy can discover itself. Off-policy methods such as supervised fine-tuning, on the other hand, can leverage external knowledge beyond the b...
Ming-Yu Chen, Ye-Fan Tao, Gerald Friedland et al.· 0 citations
Adaptive AI agents can help make BIM data more machine-readable by navigating IFC models, interpreting inconsistent information, and mapping it to defined standards. In this blog, Alok Rawat shares findings from a real-world pilot in construction workflows. The post Adaptive AI Agents in Construction Workflows appeared first on GPT-Lab.
What does it take to trust AI-driven HVAC optimization? Our AI Model Factory combines agents, machine learning, reinforcement learning and deterministic checks in a governed workflow designed for messy, real-world building data. The post We built an AI factory for HVAC control appeared first on GPT-Lab.
MIT News · Artificial Intelligence· news.mit.eduAug 18, 2026
A new method for surgically removing training examples from a model reveals that as datasets grow, the link between what a model learns and what it produces dissolves.
Microsoft Research Blog· microsoft.comJul 30, 2026
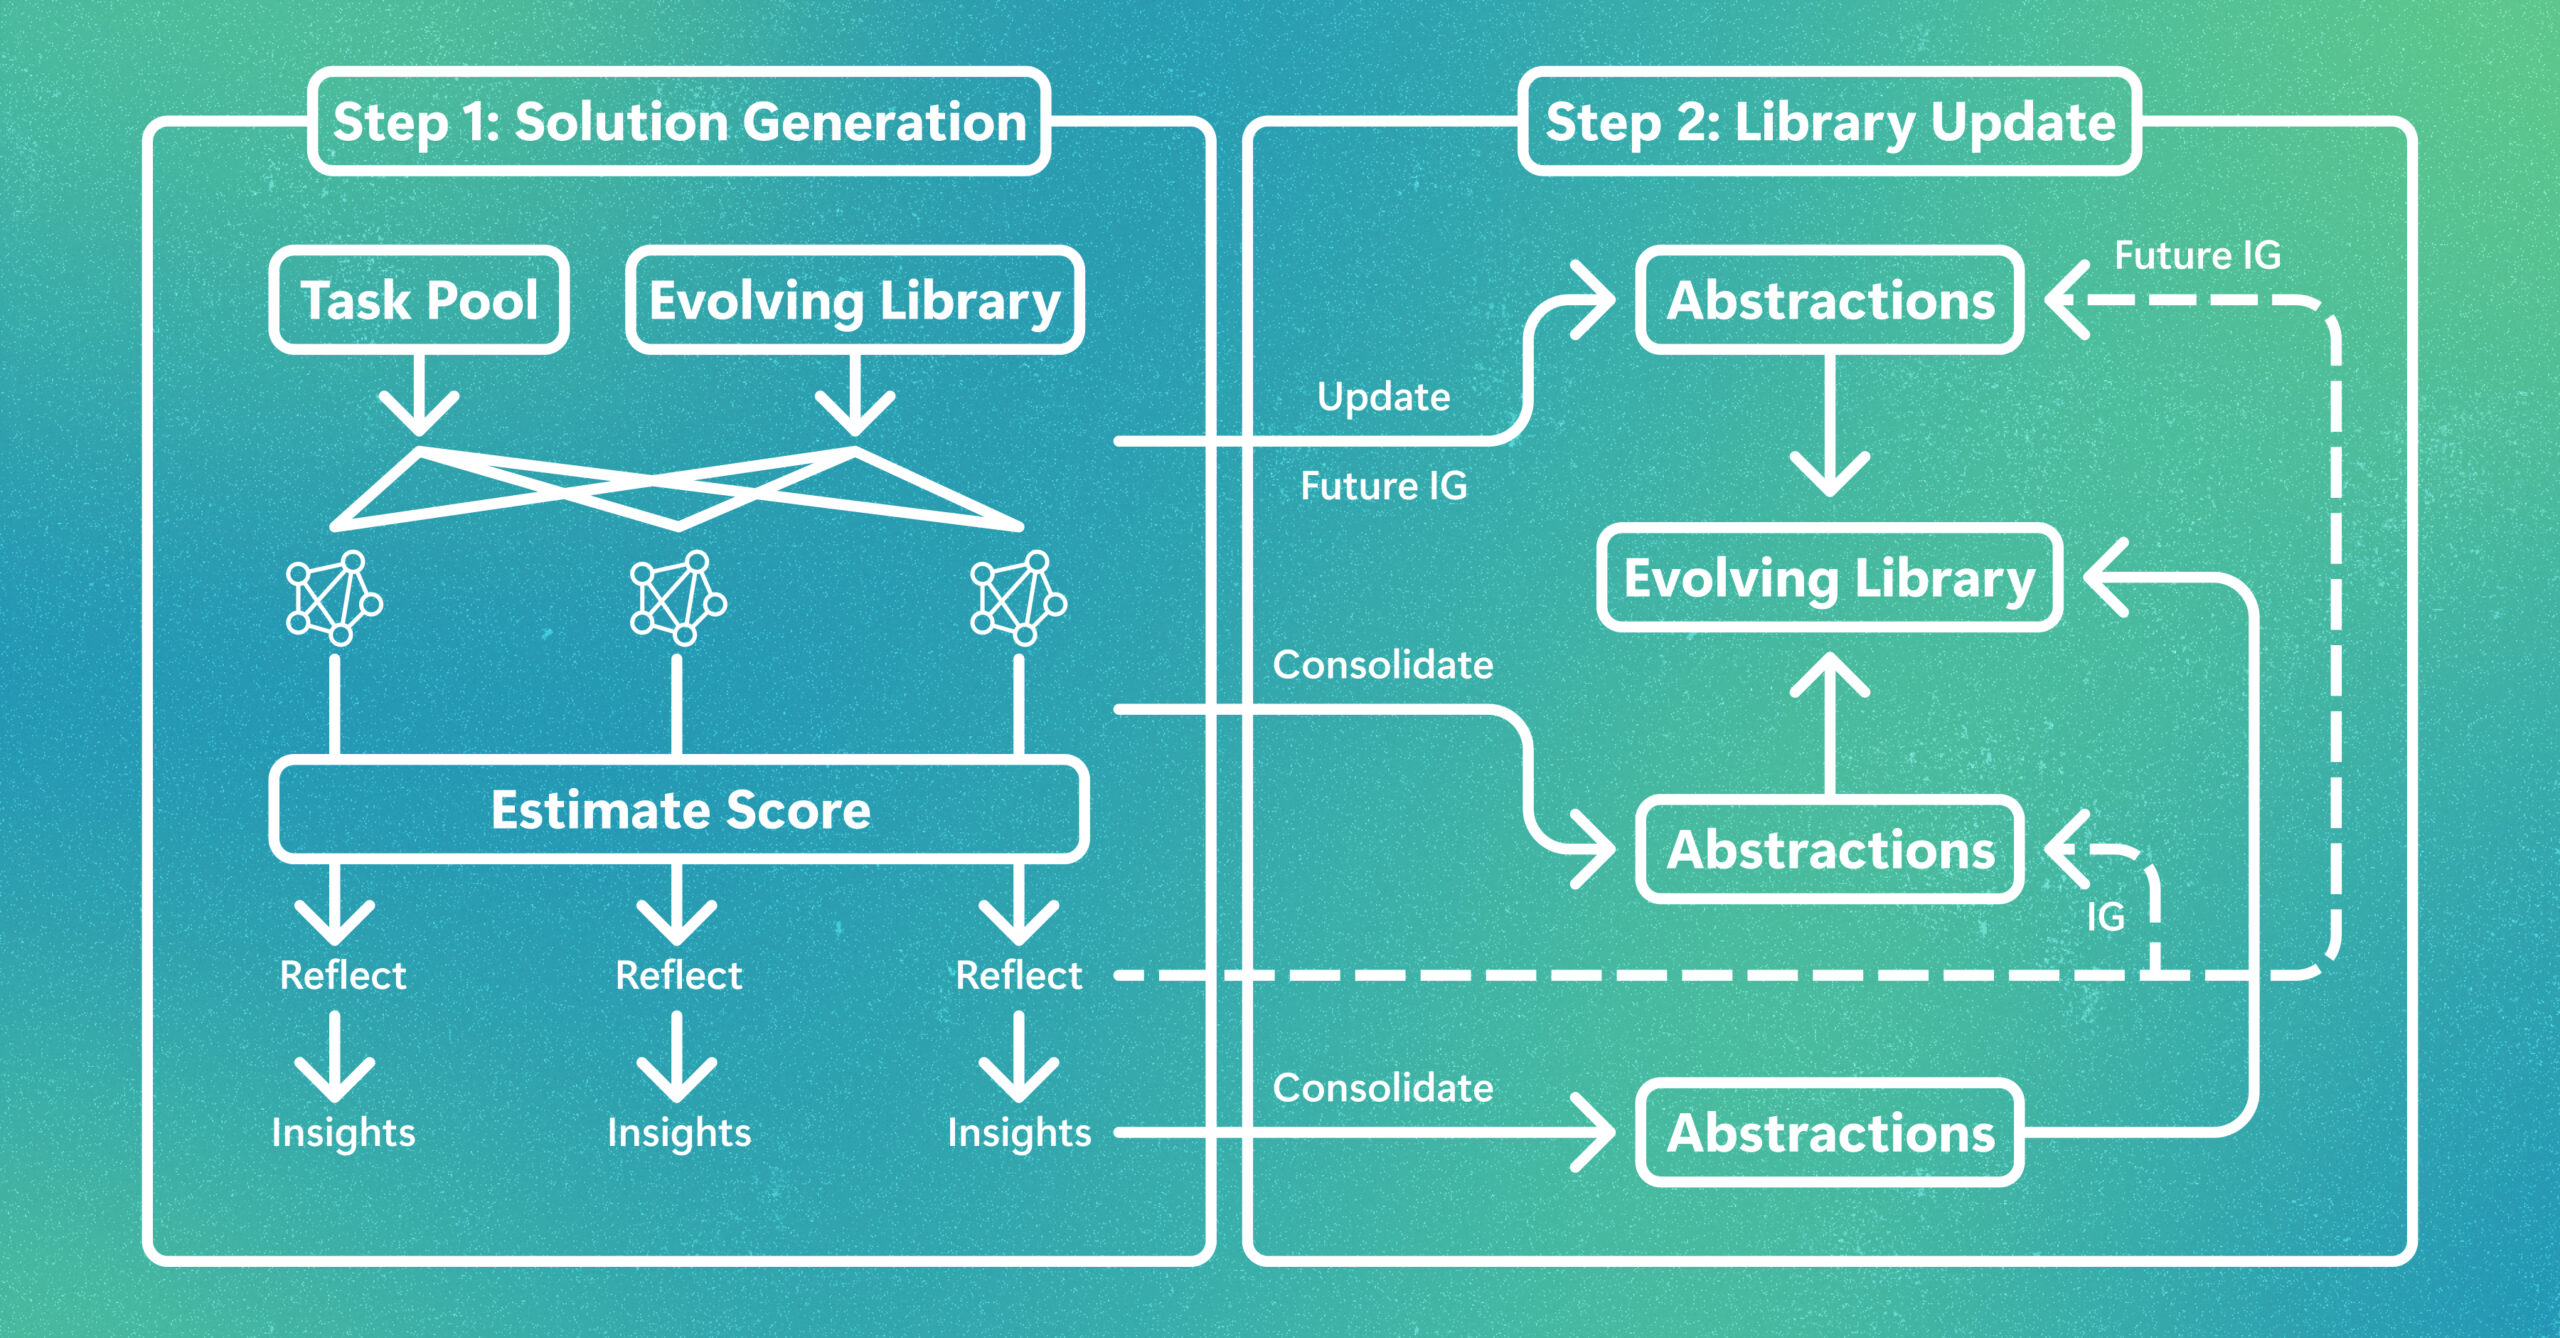
LLMs do not get smarter just by remembering more. EvoLib turns experience into evolving knowledge, taking reusable skills and insights that help models learn and adapt across tasks long after deployment. The post EvoLib: Turning experience into evolving knowledge appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.