This paper uses 119 conversations with 100 or more participants and an extensive data export, drawn from a wider set of 271 collected processes, to ask what determines the output of such a process.
Abstract
Polis is a popular democratic innovation tool that allows asynchronous citizen engagement through atomic statements: short statements that together describe a complex question, inviting the citizen to vote Agree or Disagree on each. This paper uses 119 conversations with 100 or more participants and an extensive data export, drawn from a wider set of 271 collected processes. The paper asks what determines the output of such a process. Three parties shape the result. The developer of the platform has made important design choices that restrict the outcome: the number of groups the platform is able to report (restricted to 2--5) and which statements are prioritized. The convener defines the assignment: the initial statements that set the tone, the policy that accepts or rejects new statements and who can be invited. Finally, the participant works within these boundaries. With access to less than half of the generated statements, they end up responding to more statements when their conversation seems to have an achievable number of statements to complete, than when they are presented with more statements. Due to choices such as warm path clustering, the exported resulting clustering cannot be reproduced based on the voting data. Conveners may want to re-analyse their own conversations once the process is closed, to consider the data in its entirety, and make their own analysis priorities explicit.
It is argued that LLM-based AI systems answer political questions for hundreds of millions of people is a set of policies over whom to answer, what to say, and whether to engage at all, conditional on the topic and what the system knows about the user.
This exploratory qualitative study examines how students' expectations of one process-capture platform, Turnitin Clarity, compared with their experience of using it are compared with their experience of using the platform.
J. Roe, M. University, British University Vietnam· 0 citations
Textual artifacts are sometimes valued not only for the words on the page, but for the human activity involved in producing them. The effort invested in a carefully tailored email can signal genuine interest; composing an apology might involve attending to another person's hurt and deciding how to respond; and requirin...
This paper reports on a locally motivated mixed-methods case study addressing a teaching-related suspicion held by software engineering instructors: that commit messages written by students frequently fail to serve their intended communicative role. To examine this suspicion empirically, we analyzed commit messages fro...
Gergo Balogh, P. Seres, László Tóth et al.· 0 citations
Large language models (LLMs) are increasingly embedded in knowledge work, raising the question to what extent they can systematically influence their users’ decisions—a question with commercial as well as societal stakes. Across an exploratory study and two pre-registered experiments grounded in moral foundations the...
Giles Hirst, W. Johnson, April Li et al.· Scientific Reports· 0 citations
This article argues that “AI use” is too blunt a category for judging what happens when a student writes a humanities paper with a large language model. Taking the most intensive case, a paper built with AI from research to final review, it follows the changing relation between student, model, sources, and draft. In re...
Joshua Leonardo Lupowitz· Tiempo devorado· 0 citations
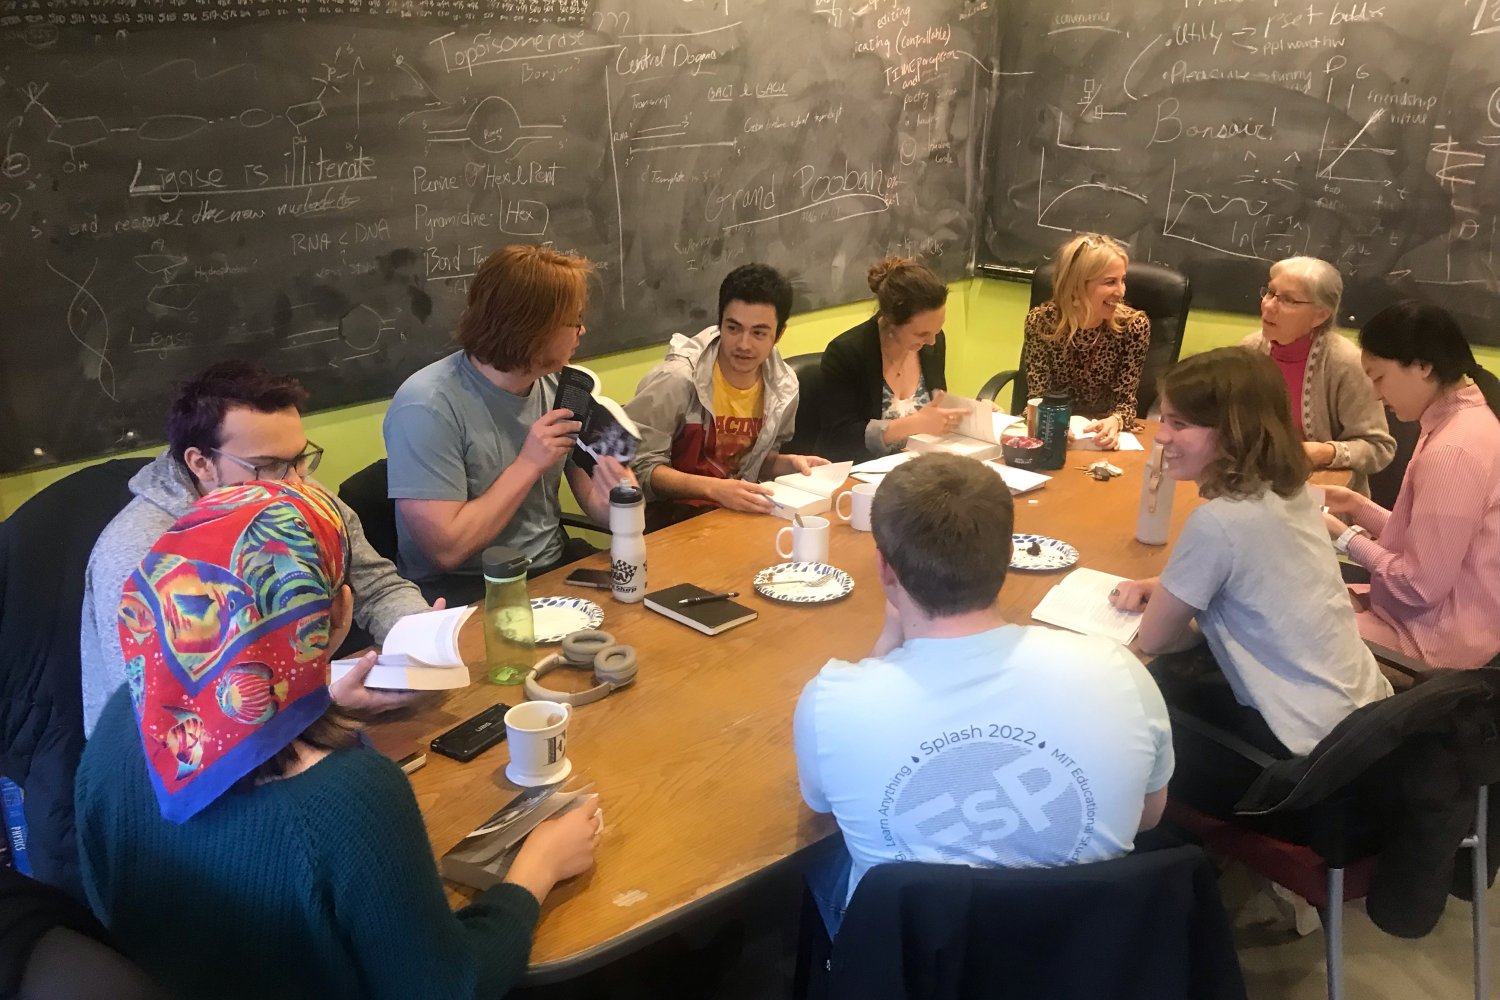
Students in MIT’s Concourse program delve deeply into the human condition, debate challenging questions, and learn to develop judgment about issues that can’t be quantified.
Jennifer Neville did not want to go into computer science—but that’s exactly where she landed. Neville discusses the starts and stops that led to her professional sweet spot and her work identifying “surprising failures” making it hard for AI to handle complexity. The post What AI gets wrong and what failure teaches us appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduSep 30, 2026
Able to defeat top-ranked human players and more efficient than other models, the new system could help decision-makers in military maneuvers or business negotiations.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.