Automated evaluation of IELTS Writing Task 2 essays requires judging task fulfilment, coherence, vocabulary, and grammar in ways that approximate trained human examiners, while remaining fast and inexpensive enough for practical deployment. This paper presents a systematic comparison of six architectures for automated IELTS essay evaluation a local generative LLM baseline (Gemma 2 9B), the same model augmented with rubric-grounded and example-grounded Retrieval-Augmented Generation (RAG), a multi-stage orchestration pipeline, a cloud-hosted LLM (Llama 3.3 70B), and a fine-tuned discriminative transformer (DeBERTa-v3-base) applied to a common 296-word benchmark essay and the same four official IELTS criteria. Rather than treating the highest observed score as evidence of accuracy, we compare scoring behavior, consistency, latency, token usage, and estimated commercial cost. Observed overall scores ranged from 6.3 to 8.5 on the 9-band scale; rubric grounding shifted the ungrounded baseline's score substantially downward (8.5 → 6.3); multi-stage orchestration improved cross-stage consistency but incurred roughly 23 minutes of total latency; and the cloud LLM offered the best latency-cost trade-off among generative approaches. The fine-tuned DeBERT a model combined the highest observed score in the final comparison with the fastest local inference (1.33 seconds) and no per-request cost. We argue that scoring reliability and explanatory quality are distinct capabilities that need not come from the same model, and propose a hybrid architecture pairing a specialized scorer with a generative LLM for feedback generation. Keywords: automated essay scoring; IELTS; large language models; retrieval-augmented generation; finetuned transformers; multi-agent evaluation; educational AI
The results are packaged in the Greenfield Startup Model (GSM), which explains the priority of startups to release the product as quickly as possible, and the need to shorten time-to-market, by speeding up the development through low-precision engineering activities.
Carmine Giardino, Nicolò Paternoster, M. Unterkalmsteiner et al.· IEEE Transactions on Softwar...· 178 citations· ⚡14
Software startup companies develop innovative, software-intensive products within limited timeframes and with few resources, searching for sustainable and scalable business models.
M. Unterkalmsteiner, P. Abrahamsson, Xiaofeng Wang et al.· e-Informatica Software Engin...· 157 citations· ⚡17
This study conducts a case survey study based on the secondary data of the major pivots happened in 49 software startups, and demonstrates that customer need pivot is the most common among all pivot types.
Sohaib Shahid Bajwa, Xiaofeng Wang, Anh Nguyen-Duc et al.· Empirical Software Engineeri...· 127 citations· ⚡15
The comparison of adopter and non-adopter sample reveals three potential adoption inhibitor, security, data privacy, and portability, which underlines the importance of the technical and security perspectives for research investigating the adoption of technology.
Nattakarn Phaphoom, Xiaofeng Wang, S. Samuel et al.· Journal of Systems and Softw...· 111 citations· ⚡8
The ongoing work building a Raspberry Pi cluster consisting of 300 nodes is presented, with potential use cases being an inexpensive and green test bed for cloud computing research and a robust and mobile data center for operating in adverse environments.
P. Abrahamsson, S. Helmer, Nattakarn Phaphoom et al.· IEEE International Conferenc...· 110 citations· ⚡7
The results indicate that software developers are a slightly happy population, but the need for limiting the unhappiness of developers remains, and 219 factors representing causes of unhappiness while developing software are identified.
D. Graziotin, Fabian Fagerholm, Xiaofeng Wang et al.· International Conference on...· 84 citations· ⚡6
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
Microsoft Research Blog· microsoft.comOct 22, 2026
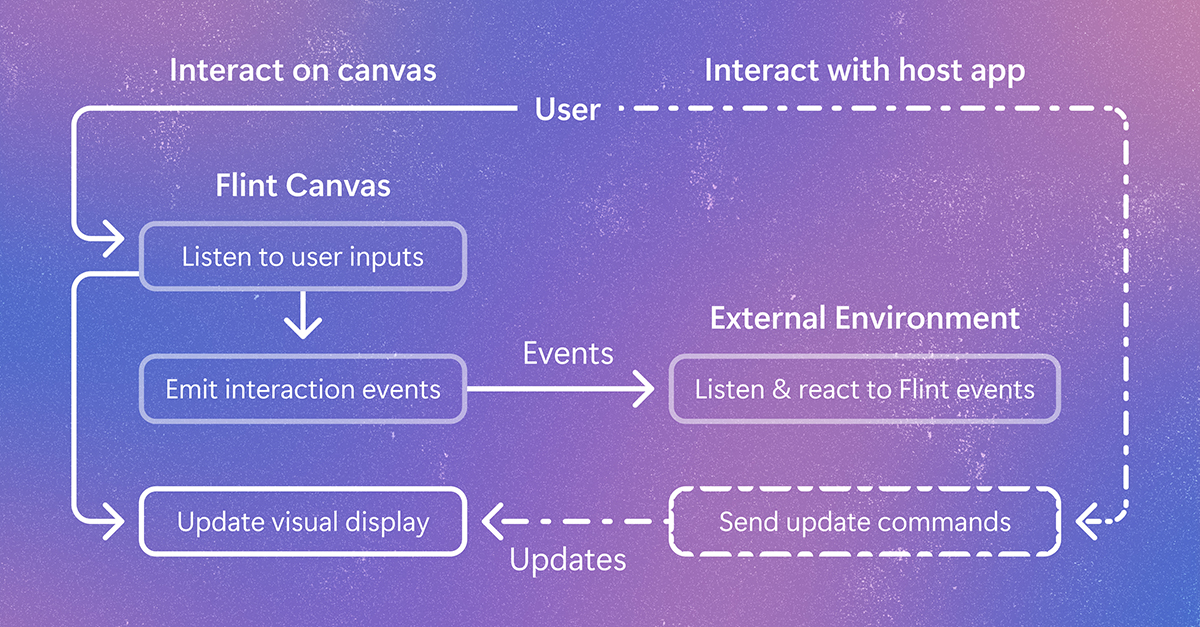
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.