We present RAGrasp, a retrieval-augmented pipeline for planar parallel-jaw grasping from a compact set of locally collected, grasp-annotated RGB-D (color and depth) templates. Unlike task-specific predictors trained primarily on large public or synthetic grasp datasets, RAGrasp requires no end-to-end retraining for a new deployment.Its template memory is constructed from observations collected with the deployment camera, robot, and gripper in the target workspace, thereby aligning stored examples with the local sensing and embodiment conditions. The system uses self-supervised DINOv2 visual fea- tures together with appearance and depth cues to prompt the Segment Anything Model 2 (SAM2), which isolates the query object. A two-stage geometry-semantic retrieval cascade then selects a template, and a confidence gate chooses one of two grasp- transfer estimators. The transferred grasp is refined using mask- support and silhouette-contact constraints before calibrated 2D- to-3D conversion. In real-world trials, RAGrasp achieves 20/20 successful grasps on seen objects and 19/20 on unseen objects. Within the evaluated setting, the results demonstrate deployment- specific grasp adaptation from limited local annotation and tolerance to the tested viewpoint and illumination changes.
GAOKAO-Bench is introduced, an intuitive benchmark that employs questions from the Chinese GAOKAO examination as test samples, including both subjective and objective questions that contribute a robust evaluation benchmark for future large language models and offers valuable insights into the advantages and limitations...
Xiaotian Zhang, Chun-yan Li, Yi Zong et al.· arXiv.org· 216 citations· ⚡17
An algorithm is proposed which leverages disentangled semantic factors to generate adversarial perturbation by altering controlled semantic attributes to fool the learner towards various "adversarial" targets.
Haonan Qiu, Chaowei Xiao, Lei Yang et al.· arXiv.org· 208 citations· ⚡17
This work proposes a HALO that directly maximizes the utility of generations instead of maximizing the log-likelihood of preferences, and suggests that the best loss depends on the inductive biases most appropriate for a given setting, an oft-overlooked consideration.
This work investigates the possibilities of using LLMs in a resume screening setting via a document retrieval framework that simulates job candidate selection and finds that the MTEs are biased, significantly favoring White-associated names in 85% of cases and female-associated names in only 11.1% of cases.
This work shows that orders of magnitude enhancement in performance could be obtained by a combination of hardware improvements and tight quantum-HPC integration and introduces high-performance architectures for quantum-probabilistic computing with custom-designed accelerators to tackle today's industry-scale classical...
Masoud Mohseni, Artur Scherer, K. Johnson et al.· arXiv.org· 121 citations· ⚡9
This paper presents a comprehensive overview of the Ultralytics YOLO family, emphasizing architectural evolution, benchmarking, deployment, and emerging directions from YOLOv5 through YOLO27, and examines detection, segmentation, depth, classification, pose, oriented detection, tracking, export, quantization, and deplo...
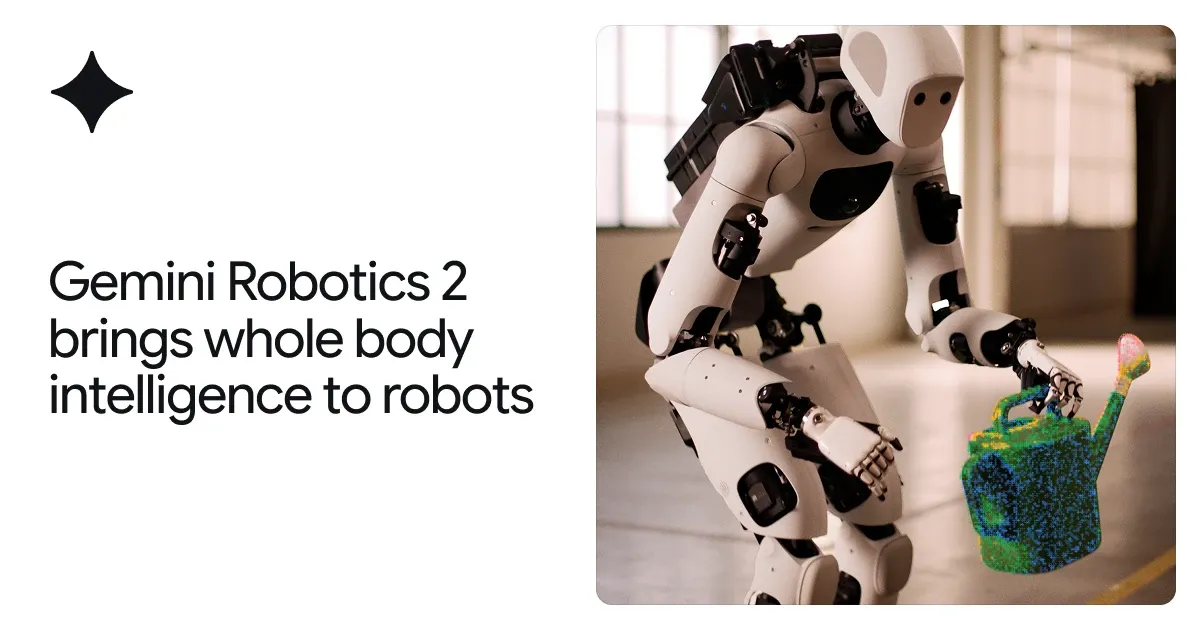
From feet to fingertips — we are teaching robots intelligent whole-body control, fine dexterity, and teamwork to complete a broad range of complex tasks.
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.