World--action models (WAMs) promise a unified model that predicts action-conditioned futures, generates feasible actions, and supports planning in imagination. However, existing joint video--action models often use computationally heavy, fixed-horizon backbones ill-suited to streaming inference and stable long-horizon open-loop rollouts. We introduce FLEX-WAM, a Flexible and Efficient Block-Causal World--Action Model for unified simulation and policy inference. FLEX-WAM supports variable-length contexts and non-causal prediction horizons, as well as infinite autoregressive generation frame by frame or block by block. Its block-causal, KV-cacheable architecture combines axial attention and blockwise diffusion forcing to enable efficient real-time rollout and deployment-time latency--throughput tradeoffs without retraining. Joint training can nevertheless produce plausible futures that weakly respond to commanded actions. We address this failure mode by balancing state and action flow-matching gradient contributions across the state--action diffusion-noise grid and regulating world-model sampling using Forward-Dynamics (FD) elasticity, an efficient training-time proxy for action responsiveness. Across simulated and real-world datasets, FLEX-WAM achieves superior multi-step prediction quality and latency while producing stable joint state--action rollouts for thousands of steps. As a joint action proposer and simulator within MCTS, it solves long-horizon PushT and all five OGBench Puzzle-4x4 tasks entirely in imagination. On a bimanual OpenArm-based robot, a single checkpoint jointly serves as a play policy and expected-outcome predictor, enabling real-time identification and collection of model--reality mismatches for future self-improvement.
GAOKAO-Bench is introduced, an intuitive benchmark that employs questions from the Chinese GAOKAO examination as test samples, including both subjective and objective questions that contribute a robust evaluation benchmark for future large language models and offers valuable insights into the advantages and limitations...
Xiaotian Zhang, Chun-yan Li, Yi Zong et al.· arXiv.org· 216 citations· ⚡17
This work proposes a HALO that directly maximizes the utility of generations instead of maximizing the log-likelihood of preferences, and suggests that the best loss depends on the inductive biases most appropriate for a given setting, an oft-overlooked consideration.
This work investigates the possibilities of using LLMs in a resume screening setting via a document retrieval framework that simulates job candidate selection and finds that the MTEs are biased, significantly favoring White-associated names in 85% of cases and female-associated names in only 11.1% of cases.
This work shows that orders of magnitude enhancement in performance could be obtained by a combination of hardware improvements and tight quantum-HPC integration and introduces high-performance architectures for quantum-probabilistic computing with custom-designed accelerators to tackle today's industry-scale classical...
Masoud Mohseni, Artur Scherer, K. Johnson et al.· arXiv.org· 121 citations· ⚡9
This paper presents a comprehensive overview of the Ultralytics YOLO family, emphasizing architectural evolution, benchmarking, deployment, and emerging directions from YOLOv5 through YOLO27, and examines detection, segmentation, depth, classification, pose, oriented detection, tracking, export, quantization, and deplo...
A novel threat is unveiled in which attackers steer the RAG system's response by injecting malicious passages into its knowledge base, enabling the attacker to steer the response without altering the user input or modifying the RAG weights.
Jiaqi Xue, Meng Zheng, Yebowen Hu et al.· arXiv.org· 109 citations· ⚡8
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduJul 30, 2026
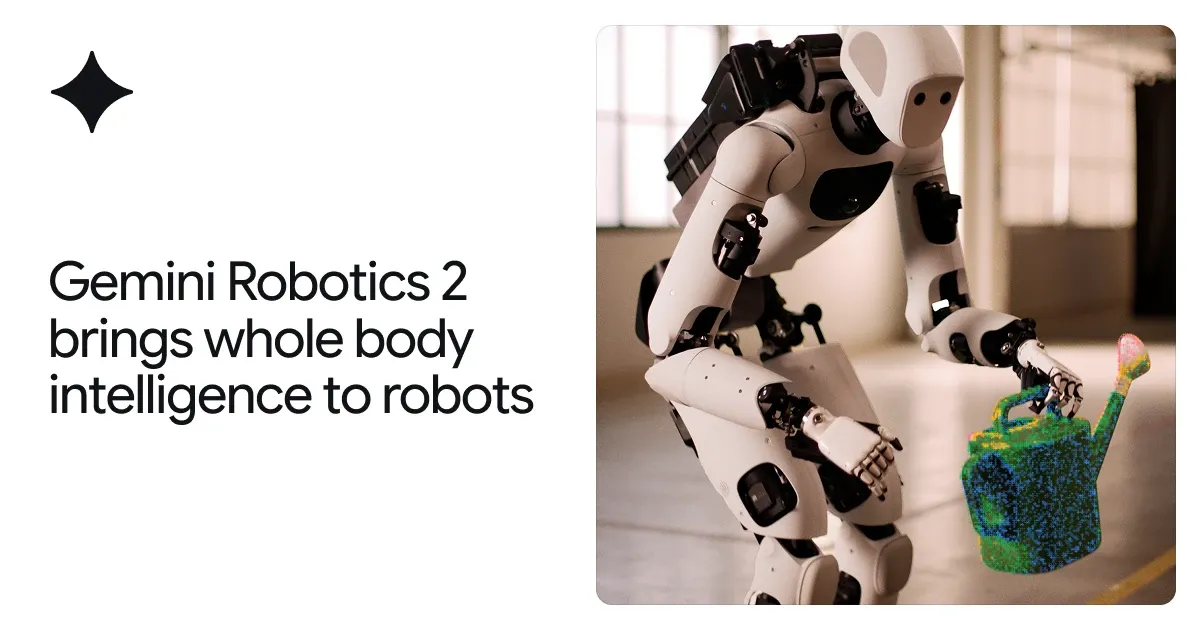
From feet to fingertips — we are teaching robots intelligent whole-body control, fine dexterity, and teamwork to complete a broad range of complex tasks.
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.