Skip to content

The Dichotomy Between Pattern Recognition and Step-by-Step Reasoning

Oct 2026 · 0 citations · 55 references
Computer Science Physics

Abstract

We argue that pattern recognition and step-by-step reasoning are two ends of a spectrum. A large language model (LLM) learns to reason step-by-step when data is structured such that the next token depends on a small amount of preceding context. Inference in LLMs resembles pattern recognition when the next token depends on a large amount of preceding context. If the next token depends on only the $c$ most recent tokens, reasoning traces are paths on a De Bruijn graph whose nodes are $c$-length contexts and edges are next-token transitions between contexts. The set of reasoning traces of a task forms a directed acyclic subgraph of the De Bruijn graph. An LLM that has learned all edges of this subgraph can compose them to solve longer, unseen tasks, i.e., it reasons step-by-step. We prove that the number of edges is vanishingly small compared to the number of reasoning traces. Empirically, the number of training samples a transformer needs is a power law in the number of edges, so learning to reason step-by-step is sample efficient. We can induce De Bruijn structure in any task by maintaining a ``state''that makes future reasoning independent of the past. The frequency of states in the reasoning trace determines $c$. We show, by fine-tuning Qwen2.5-1.5B-Instruct to solve equations and answer questions about stories, that frequent states (small $c$) result in higher accuracy but greater fragility to perturbations at test time. LLMs trained with a large $c$ are only as good as models that perform pattern recognition without reasoning. A moderate density of states balances accuracy and robustness. We show that real-world data has De Bruijn structure: Qwen3-14B and Qwen3-32B retain over 75% of their accuracy on GSM8K, MATH-500 and GPQA-Diamond when attention is restricted to a sliding window less than 15% as long as the full reasoning trace.

View source

Similar papers

#small language model Dataset Open access Oct 2026

Socratic guiding questions in synthetic arithmetic data: matched LoRA runs (revision v2)

Supporting data, adapters, predictions and code for the article *Low-Cost LoRA Fine-Tuning of Small Language Models for Multi-Step Arithmetic Reasoning* by Jake O'Grady, Asena Isik Gürhan, Chee Fong Ting and Effirul Ramlan (University of Galway). We generated 20,000 GSM8K-derived arithmetic problems with step-by-step s...

O'Grady, Jake, Gürhan, Asena Isik, Chee, Fong Ting et al. · 465 citations
#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54

Diffusion models as plug-and-play priors

The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.

Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al. · 316 citations · ⚡15

Trajectory Balance: Improved Credit Assignment in GFlowNets

It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...

Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al. · 302 citations · ⚡60

KTO: Model Alignment as Prospect Theoretic Optimization

This work proposes a HALO that directly maximizes the utility of generations instead of maximizing the log-likelihood of preferences, and suggests that the best loss depends on the inductive biases most appropriate for a given setting, an oft-overlooked consideration.

Kawin Ethayarajh, Winnie Xu, Niklas Muennighoff et al. · 195 citations · ⚡28

Related blog posts

MIT News · Artificial Intelligence Oct 23, 2026

Q&A: How AI came to model the “messy” human mind

Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.

Microsoft Research Blog Oct 12, 2026

Simulating student learning for better AI tutoring

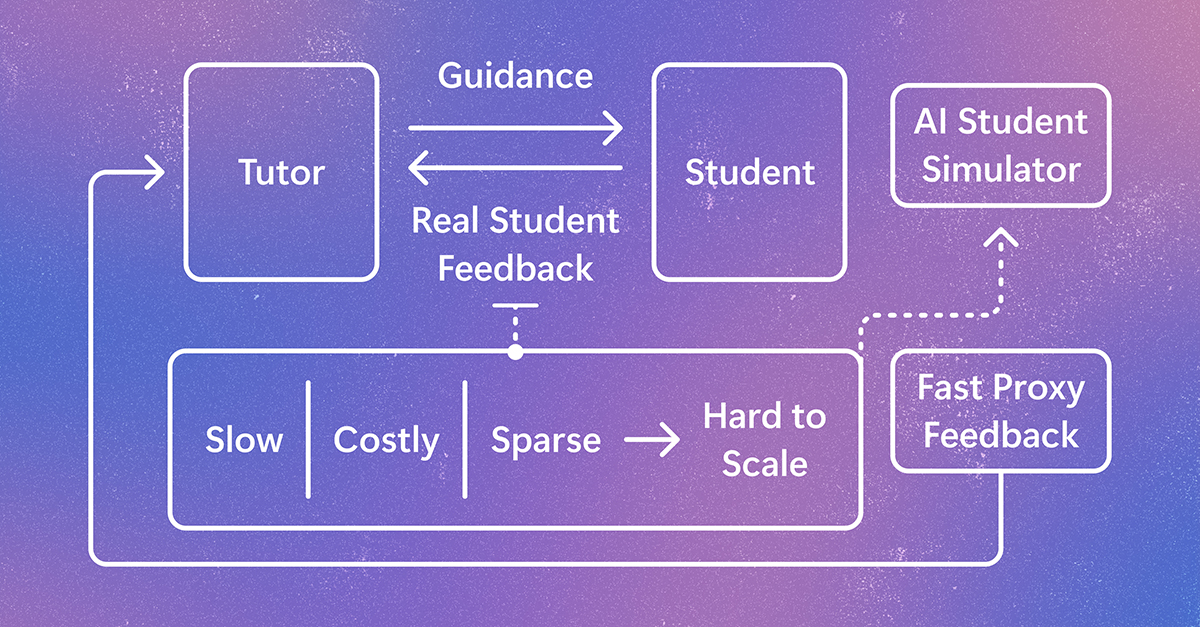
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.