Skip to content

MUSE: A Run-Centric Platform for Multimodal Unified Safety Evaluation of Large Language Models

Mar 2026 · arXiv.org · Vol abs/2603.02482 · 0 citations · 26 references
Computer Science Engineering

TL;DR

MUSE (Multimodal Unified Safety Evaluation), an open-source, browser-based, run-centric platform for multimodal safety evaluation, demonstrates the value of run-centric, fine-grained evaluation for characterizing multimodal safety behavior beyond a single binary success metric.


Abstract

Safety evaluation of multimodal large language models requires tracking not only whether an attack succeeds, but also how the interaction unfolds across turns and input modalities. We present MUSE (Multimodal Unified Safety Evaluation), an open-source, browser-based, run-centric platform for multimodal safety evaluation. MUSE treats each attack run as the persistent unit of execution, inspection, and analysis, preserving its configuration, multi-turn trajectory, delivered modalities and media, target responses, and safety judgments. A five-level response taxonomy further distinguishes full Compliance from Partial Compliance and refusal behavior, yielding hard ASR, soft ASR, and gray-zone width (GZW). Across 11,700 evaluations on six multimodal LLMs, direct text-only requests yield only 3.1% macro hard ASR and 4.4% soft ASR, while iterative attack procedures are substantially more effective. Attack effectiveness also varies substantially with the attacker backbone. In contrast, Inter-Turn Modality Switching (ITMS), evaluated as a controlled delivery-modality probe, does not consistently increase attack success. These results demonstrate the value of run-centric, fine-grained evaluation for characterizing multimodal safety behavior beyond a single binary success metric.

View source

Similar papers

Preprint Aug 2026

ReFrame: Evidence-Guided Test-Time Safety Alignment in Multimodal Large Language Models

ReFrame is a training-free multimodal input reframing framework where two agents share a lightweight locally deployed MLLM: the evidence-generation agent constructs complementary risk and utility evidence, and the rewrite-and-routing agent converts it into a safe proxy prompt and image-routing decision before calling t...

Wenzheng Jiang, Xuan-Kun Rong, Yuan-Zhao Zhai et al. · 0 citations
Preprint Aug 2026

COMIC: Reference-Aware Safety Gating for Multimodal Large Language Models

It is suggested that multimodal safety cannot be enforced reliably without modeling the requested operation, the visual target to which it applies, and the confidence of that grounding.

Md Abdullahil Oaphy, Anhao Xiang, Zongxing Xie et al. · 0 citations
Review Open access Sep 2026

A Comprehensive Survey on Code-Switched LLM Safety and Robustness Evaluation

This survey provides the first comprehensive review of research on code-switched LLM safety and robustness evaluation, and aims to guide researchers and practitioners in developing more robust evaluation frameworks and alignment techniques for real-world multilingual deployments.

Pulagam Naveen Kumar, Sowjanya Bojja, K. Anoosha et al. · 0 citations
Book Open access Aug 2026

OmniVul: A Holistic, Multi-Turn Conversational Benchmark for LLM-Based Vulnerability Assessment

With more than 20,000 Common Vulnerabilities and Exposures (CVEs) reported annually, software vulnerabilities represent a critical cybersecurity challenge. This volume has intensified the demand for automated detection and analysis, motivating the integration of large language models (LLMs) for such tasks. However, exi...

Vishnu Teja Kandalam, Viet Duong, Xiaochang Li et al. · 0 citations
#artificial intelligence Preprint Sep 2026

An Experimental Evaluation of Multimodal Prompt Injection Attacks on Agentic AI Frameworks

This work presents MMPIBench, a reproducible benchmark that measures how far each injected instruction travels through the agent, from perception through planning to the tool call, and extends the benchmark to audio, the only other raw perceptual channel current frontier models accept.

V. Nguyen, Mohammad I. Husain · 1 citation

Related blog posts

MIT News · Artificial Intelligence Aug 27, 2026

Looking beyond natural sequences

A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.

Microsoft Research Blog Aug 11, 2026

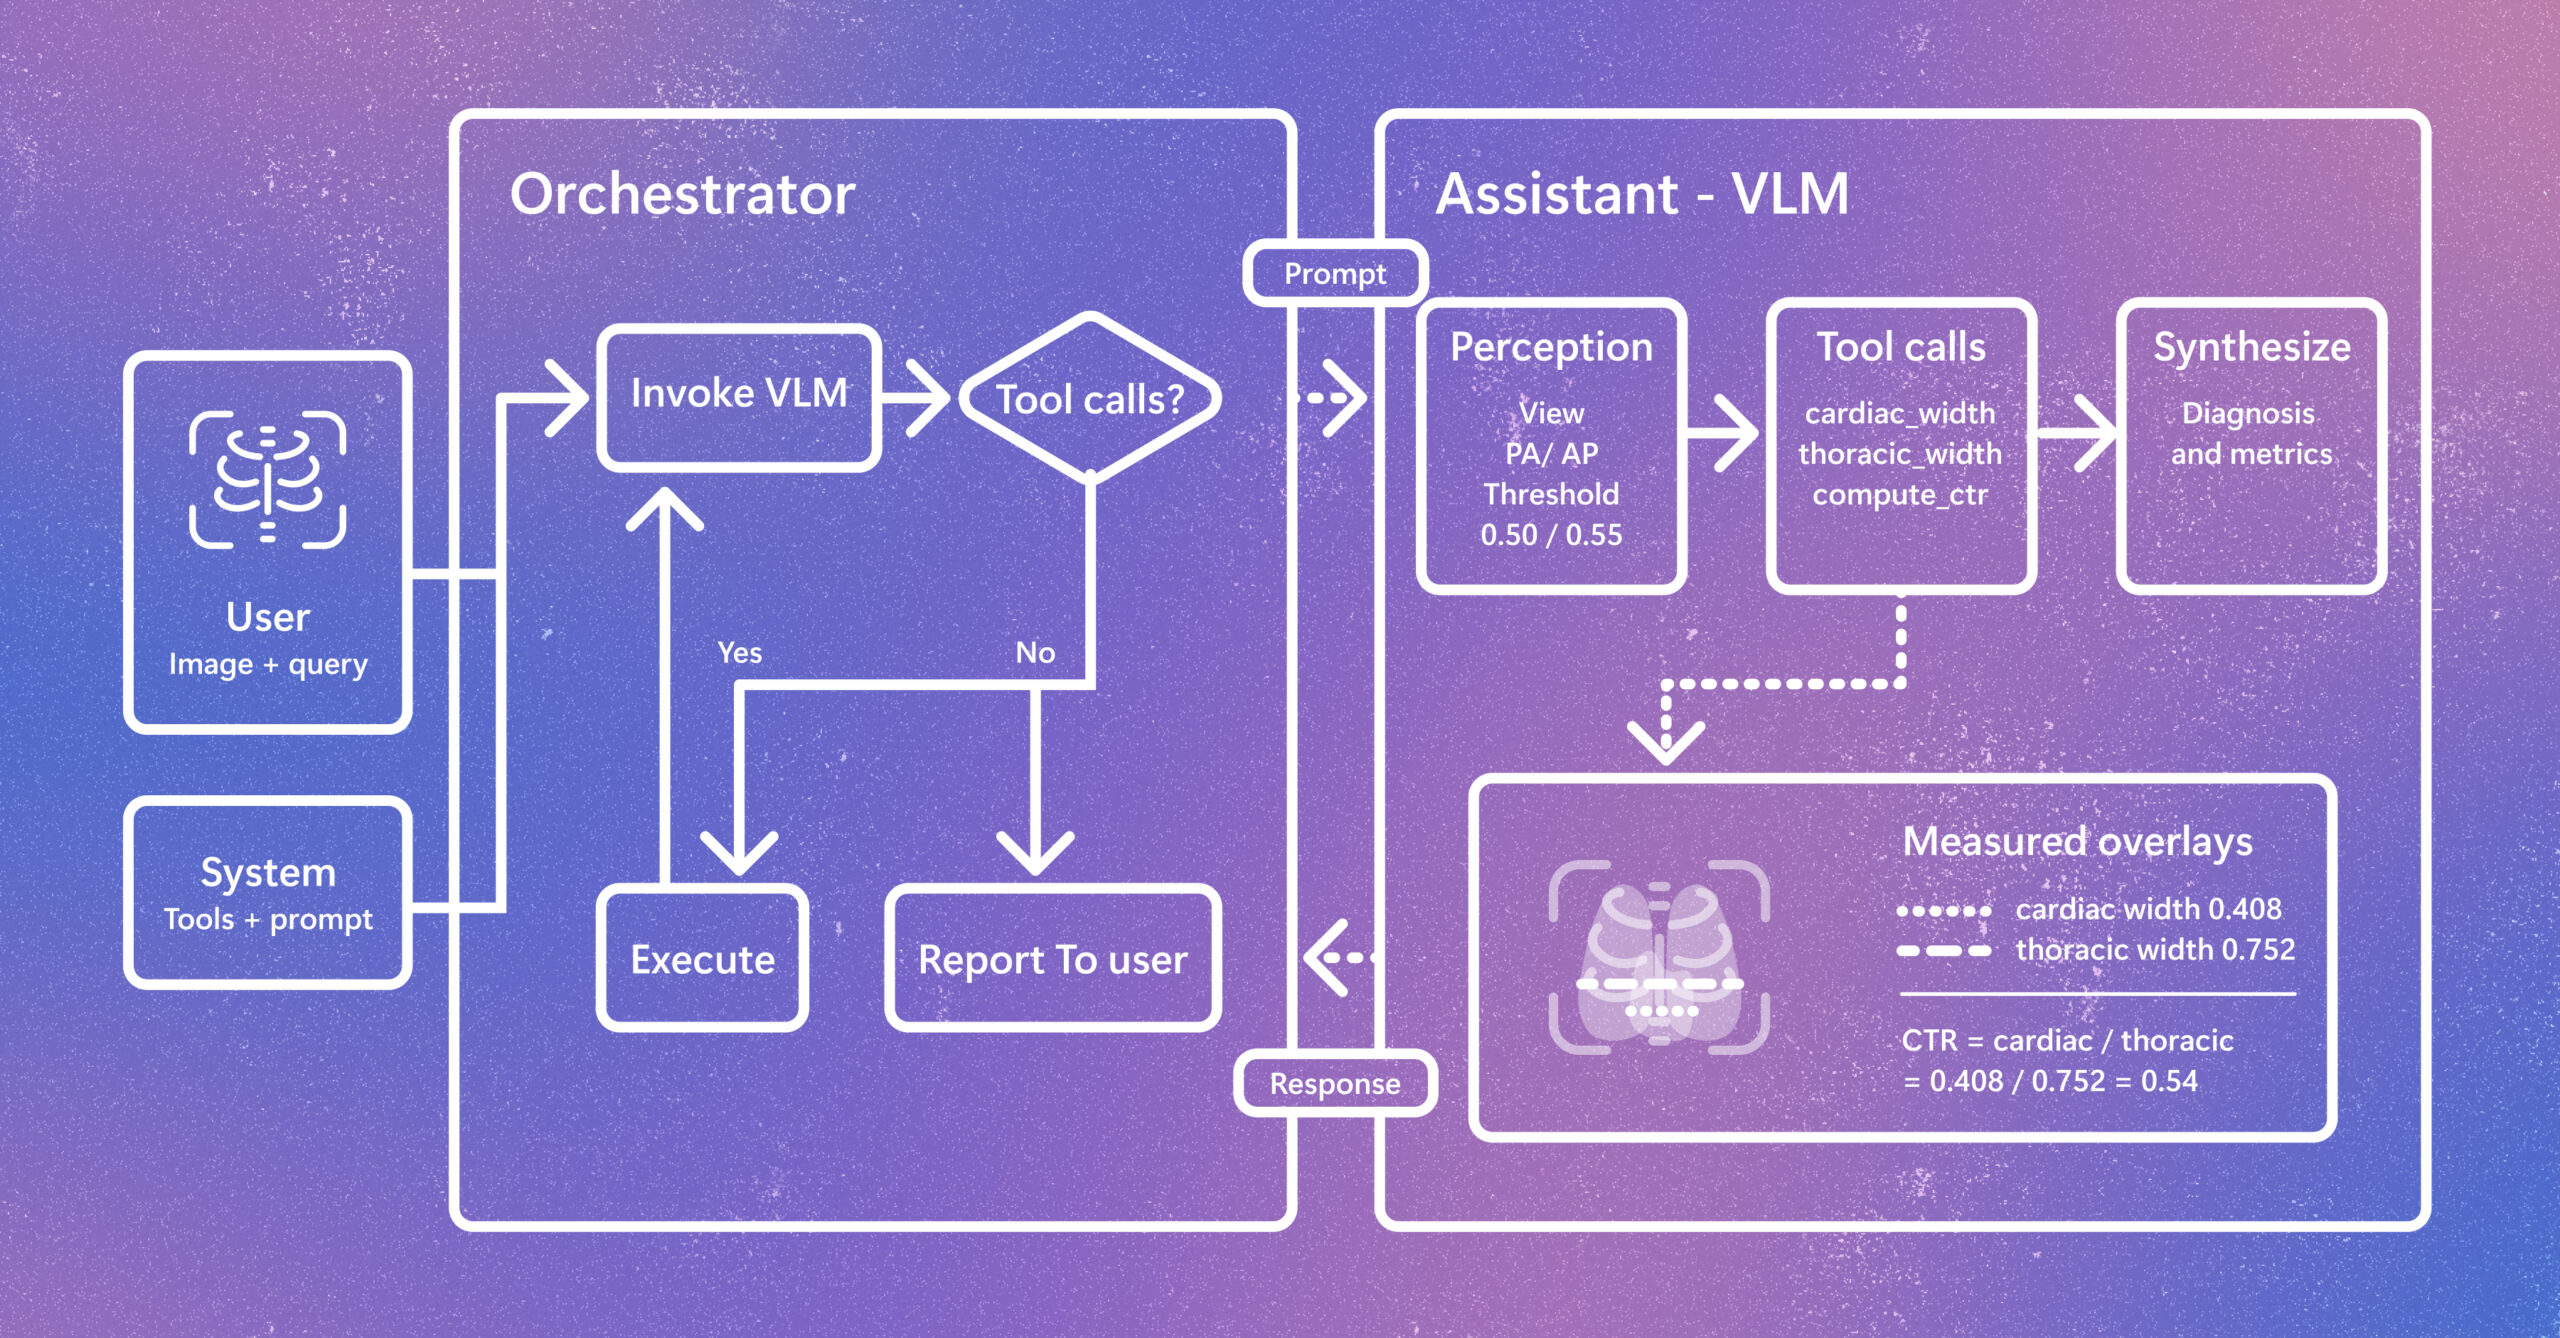
Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.