Skip to content
#machine learning #computer vision Preprint Open access

How Vision Transformers Represent Position: A Mechanistic Comparison of Absolute and Rotary Positional Encodings

Mahmoud Mannes Nikhil Maturi Parva Mehta Jiwon Jeong Aravind Singaram Kannappan
Oct 2026
Machine Learning Computer Vision

Abstract

Positional embeddings encode the spatial position of each image patch in a Vision Transformer (ViT), allowing the model to distinguish different spatial arrangements of visual content. However, we know little about how the choice of embedding shapes a vision transformer's internal representation. In this work, we show that Absolute Positional Embeddings (APE) and Rotary Positional Embeddings (RoPE) encode spatial position through different internal mechanisms: APE stores position in explicit features, while RoPE builds it inside attention and rebuilds it when it is withheld. Specifically, in APE models, sparse autoencoders recover causal row- and column-specific features, whereas interventions on RoPE reveal distinct rotary components that separately encode row and column information. Additionally, causal interventions selectively disabling RoPE's row or column rotations show that decodable row and column information can be independently removed and, once rotations are restored, partly reconstructed, in part by axis-specialized attention heads. Both mechanisms are causally important for classification: permuting APE's positional features across patches reduces top-1 accuracy by 24--31 points, and ablating the rotations of RoPE's primary rebuilding head reduces it more than ablating those of any other head. Our findings show that the choice of positional encoding fundamentally changes how spatial information is organized and processed inside Vision Transformers. More broadly, our work demonstrates how mechanistic analysis can reveal how models construct, reconstruct, and maintain structured representations, providing a basis for targeted interventions in vision models.

View source

Similar papers

#artificial intelligence Conference Open access Jun 2018

Gibson Env: Real-World Perception for Embodied Agents

This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.

F. Xia, Amir Zamir, Zhi-Yang He et al. · 1,069 citations · ⚡112
#computer vision Review Sep 2017

Agile Software Development Methods: Review and Analysis

This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.

P. Abrahamsson, O. Salo, Jussi Ronkainen et al. · 727 citations · ⚡54
#computer vision Jun 2008

The impact of agile practices on communication in software development

The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.

M. Pikkarainen, Jukka Haikara, O. Salo et al. · 401 citations · ⚡48
#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54

Diffusion models as plug-and-play priors

The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.

Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al. · 316 citations · ⚡15

Related blog posts

Microsoft Research Blog Aug 11, 2026

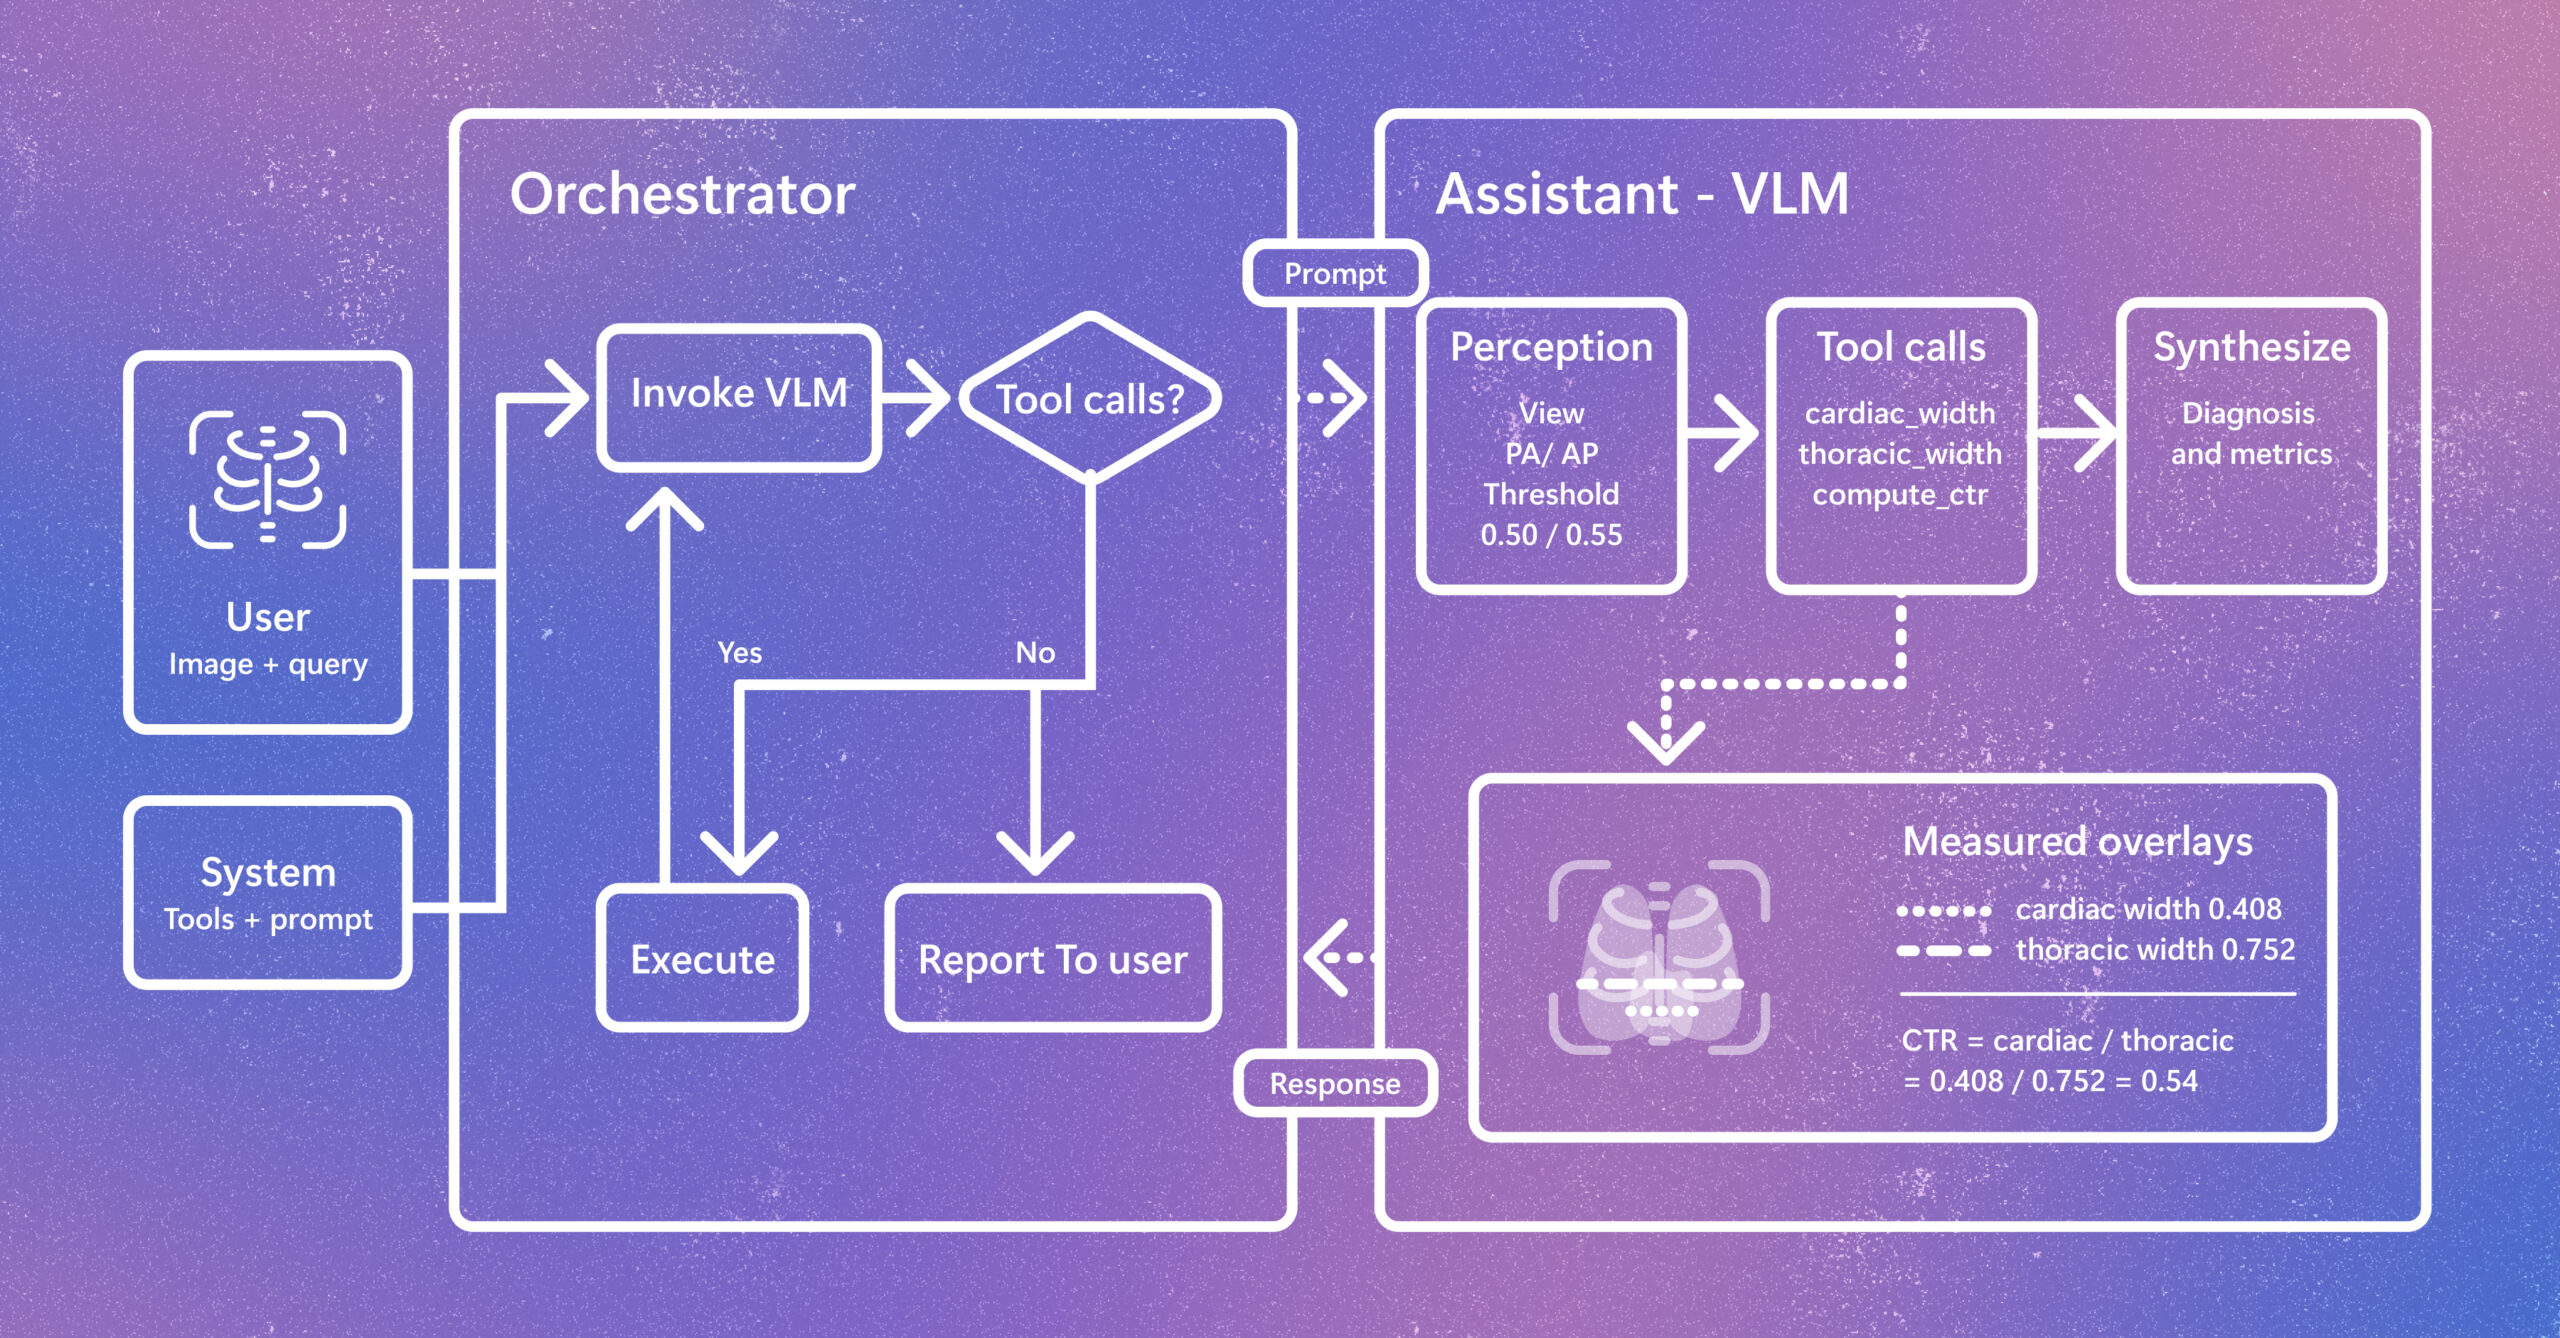
Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

MIT News · Artificial Intelligence Oct 23, 2026

Q&A: How AI came to model the “messy” human mind

Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.