Elephant in the Fridge: Constant-Memory Frame Packing for Long Video Understanding
Shuo GaoChenhao ZhengZhongzheng Ren
Oct 2026
Machine LearningComputer Vision
Abstract
Hour-long videos, streaming feeds, and movie-length content are pushing vision-language models (VLMs) past their breaking point -- the standard recipe of encoding each frame into visual tokens yields sequences that grow linearly with video length, causing prohibitive memory consumption and inference latency. Existing approaches, such as token reduction and keyframe selection, shorten the token sequence but leave the O(n) scaling intact, failing to resolve the fundamental bottleneck. We propose FramePack-U, a strikingly simple, training-free frame packing framework that compresses arbitrarily long videos into a fixed size visual representation at constant memory cost. FramePack-U requires no fine-tuning or architectural modification -- it plugs directly into off-the-shelf VLMs at inference time. Inspired by FramePack from the generation literature, we propose a content-aware compression strategy for visual understanding under a fixed token budget. Specifically, FramePack-U (1) scores each frame by its semantic similarity to the text prompt and ranks frames in a diversity-driven manner, and (2) packs the selected frames at varying resolutions into a fixed-length context window. This concentrates the memory budget on frames that are both instruction-relevant and visually diverse. While FramePack-U can in theory pack arbitrarily many frames into the fixed budget, we identify an empirical instantiation that generalizes robustly across settings. Extensive experiments on LongVideoBench, MLVU, and Video-MME show that FramePack-U consistently outperforms full-resolution baselines and prior token reduction and keyframe selection methods across diverse model families, parameter scales, and frame budgets. Notably, on Qwen3.5-35B-A3B with a 128-frame budget, FramePack-U yields gains of +12.9\%, +10.6\%, and +9.7\% over the official model on the three benchmarks, respectively.

This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.
F. Xia, Amir Zamir, Zhi-Yang He et al.· 2018 IEEE/CVF Conference on...· 1,069 citations· ⚡112
This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.
P. Abrahamsson, O. Salo, Jussi Ronkainen et al.· arXiv.org· 727 citations· ⚡54
The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.
M. Pikkarainen, Jukka Haikara, O. Salo et al.· Empirical Software Engineeri...· 401 citations· ⚡48
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
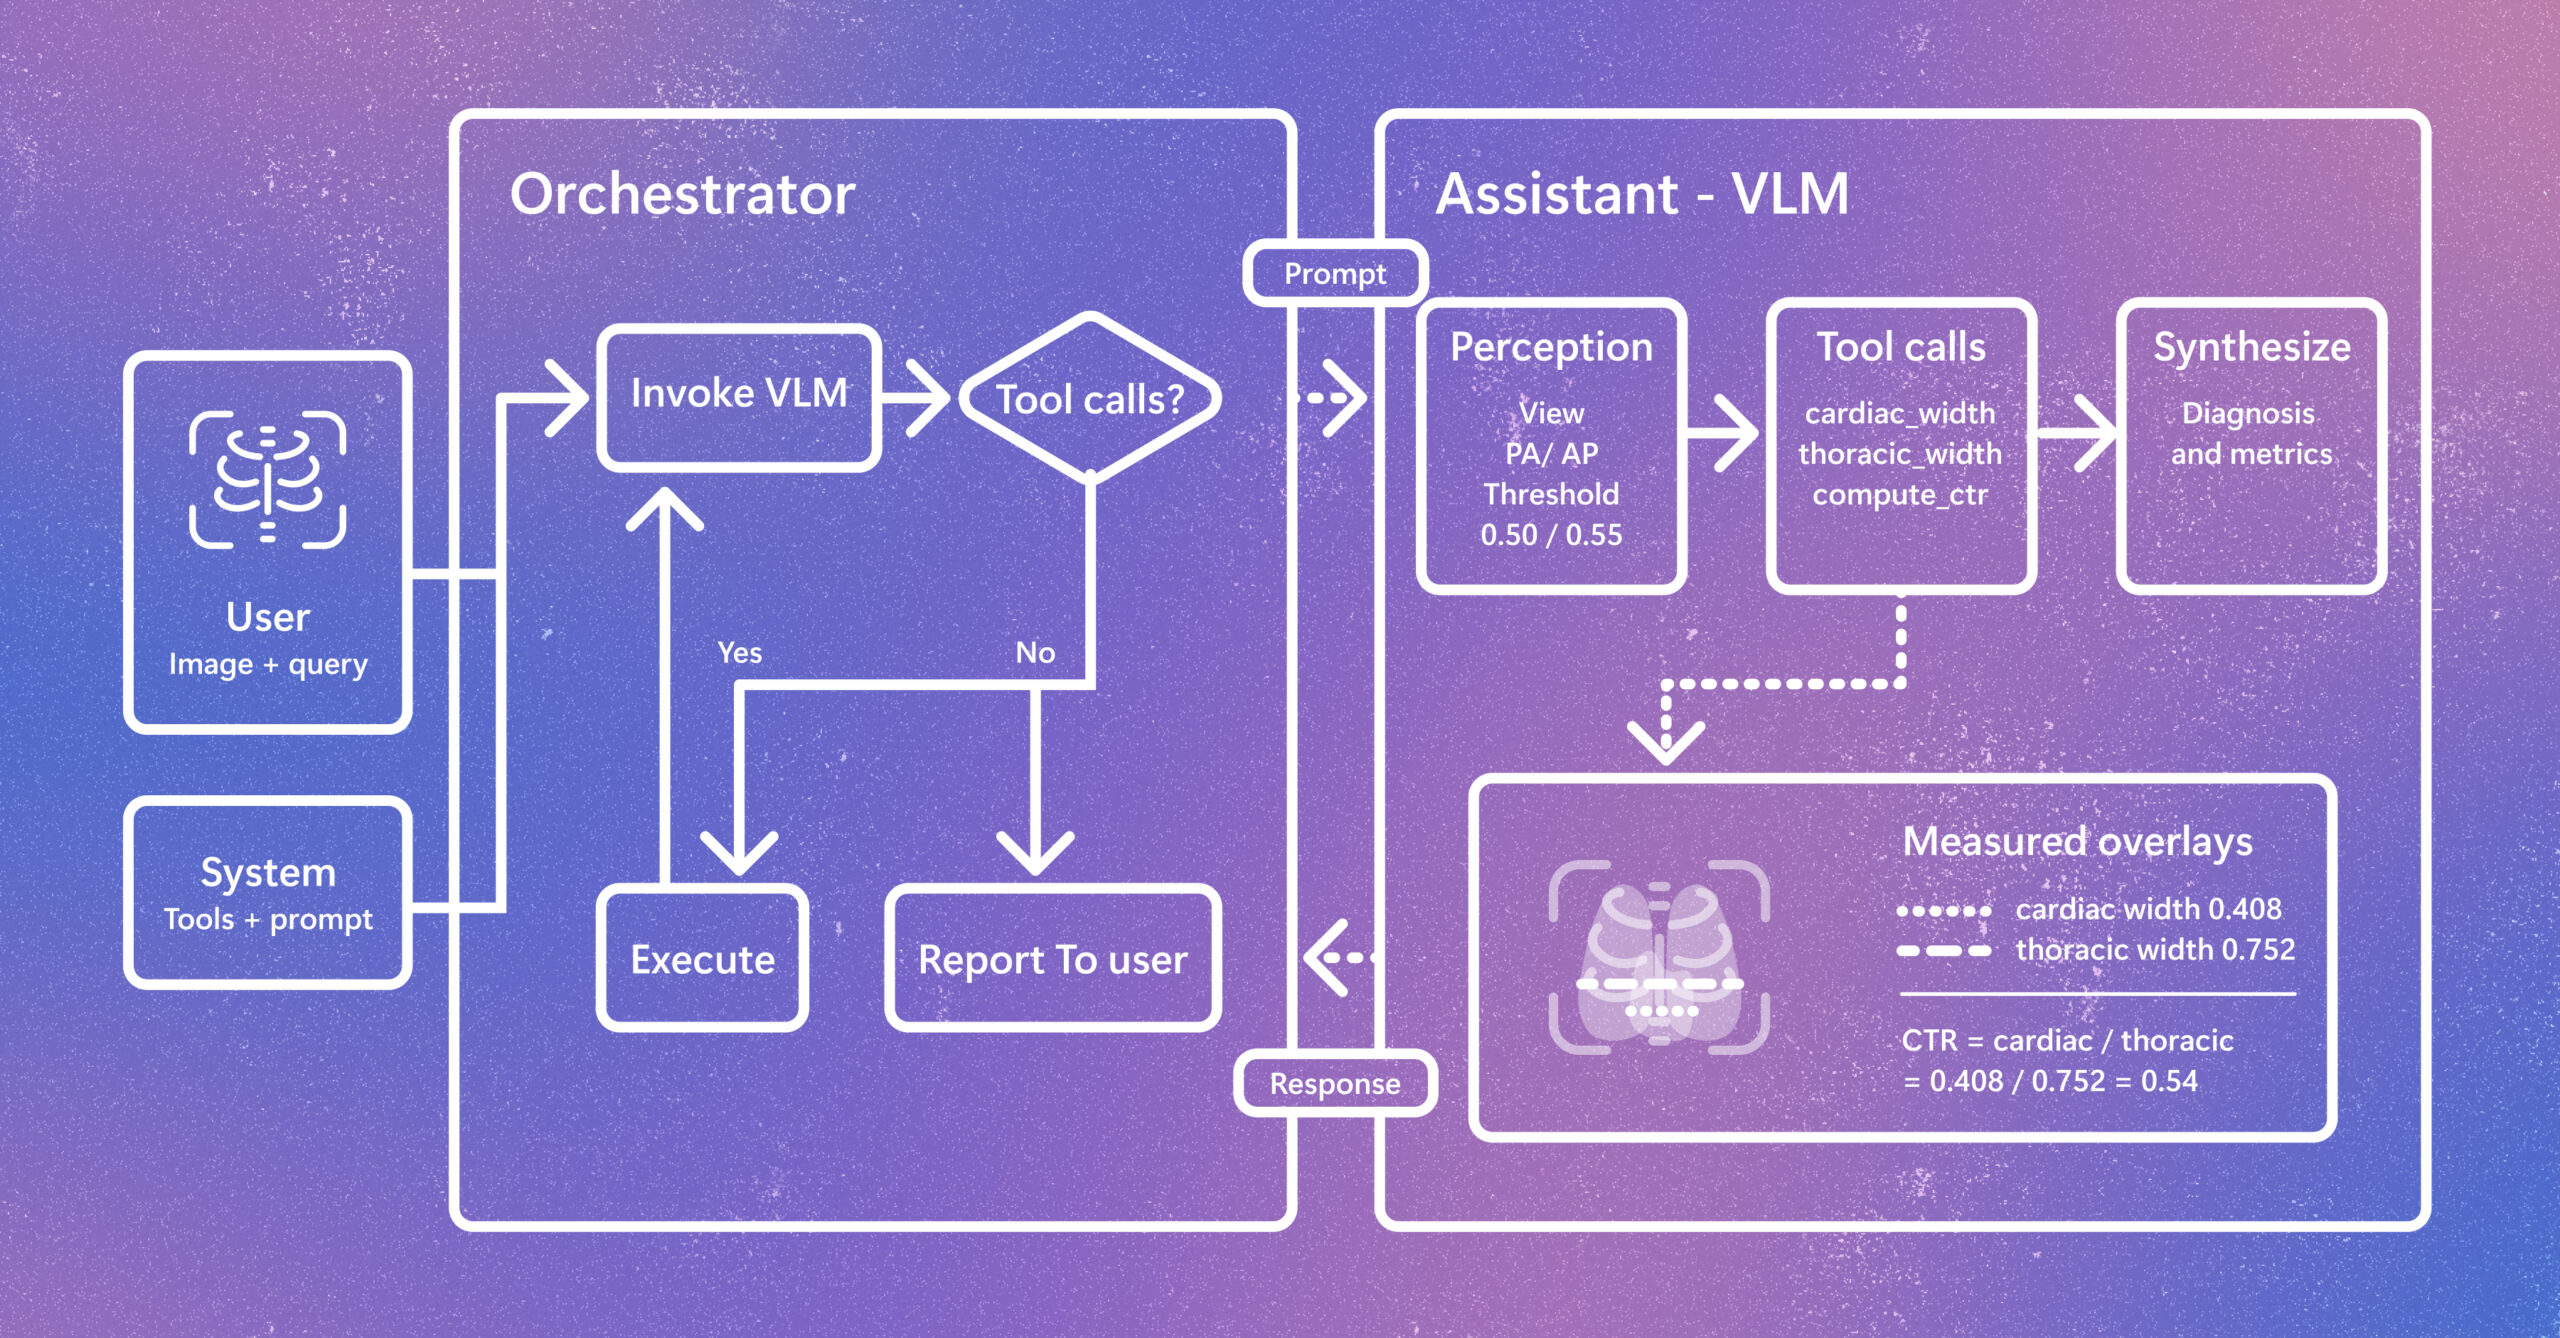
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.