Direct Preference Optimization (DPO) typically relies on preference pairs generated from diverse model pools and ranked by an external LLM judge. The recently proposed delta-learning hypothesis suggests that comparable supervision can instead be obtained from a single pair of models by treating the larger model's respo...
G. Curci, S. Simonazzi, Andrea Molinari et al.· 0 citations
Audit-based certification bounds the violation rate of an LLM agent by auditing a random fraction $\varepsilon$ of actions and reweighting the audited labels; its validity is meant to rest only on the defender's audit coin. We show that it also rests on a confidentiality property: the coin must not interfere with the a...
Multimodal perception forms the foundation of multimodal intelligence. In particular, spatial perception and multimodal long-context understanding are two pivotal tasks that underpin embodied AI and multimodal agents. However, synthesizing targeted, high-quality training data for these tasks remains difficult and costl...
Reliable crop-yield prediction can support agricultural planning and resource allocation. This study evaluates five regression models for predicting crop yield from environmental, crop-related, and agricultural management variables. The dataset initially contained 1,000,000 observations and ten variables, with 231 obse...
Saptak Das, Arijit Sarkar, Soumik Neogi et al.· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Embedding-level scaling expands the capacity of language models through lookup-based memory rather than by increasing model depth, width, or dense computation. Extending this idea to vision-language models (VLMs) is challenging because visual features are continuous, spatially structured, and query-dependent, unlike di...
Miso Choi, Daekeun Kim, Eunji Kim et al.· 0 citations
It is shown that advancement requires a correctable train-target gap, and the condition is operationalized as the $\Delta$-test, an observable discrepancy between the uncurated baseline's training and target losses that is computable prior to expensive curation.
Jia-Xing Wang, Zi-Cheng Zhang, De-Ping Xiang et al.· 0 citations
DCKV, a differentiable codec for the KV cache and the first KV-cache codec that is trained end to end, is presented, a differentiable codec for the KV cache and the first KV-cache codec that is trained end to end.
Egor Maximov, Aleksei Merkelov, Vasiliy Alekseev et al.· 0 citations
Reinforcement Learning with Verifiable Rewards (RLVR) derives its learning signal from binary rewards via on-policy exploration and becomes a powerful paradigm for improving the reasoning of large language models. Yet it faces a learning cliff on problems beyond model's current ability: when every rollout fails, the sa...
Ze-Hao Wang, Han-Zhu Chen, Run-Quan Gui et al.· 1 citation
Pretrained video generation models encode rich priors about physical interactions, but leveraging them for robot control typically requires either resource-intensive video generation at test time or action heads trained from scratch that do not fully utilize the pretrained backbone. We introduce Tokenizing Actions as V...
Jeremy A. Collins, Seungjae Lee, Rachanon Wachakorn et al.· 0 citations
Rubric-based reinforcement learning uses fine-grained grader feedback to train large language models on open-ended tasks, but grader randomness can alter GRPO updates in ways that score discrepancies alone cannot characterize. Because GRPO jointly normalizes rewards within each response group and combines the resulting...
Jiale Huang, Zixu Li, Zhiwei Chen et al.· 0 citations
Test-time training (TTT) enables a deployed language model to internalize incoming context on-the-fly into a small set of fast-weight parameters, rather than merely treating it as transient context for attention. In-Place TTT recently made this idea practical for large language models by repurposing the down-projection...
Yue Wu, Yang Zhang, Wei-Nan Gan et al.· 0 citations
Gradient-based data attribution has become an important tool for high-quality data selection in the instruction fine-tuning of large language models (LLMs), as it estimates the contribution of training examples through their influence on model optimization. However, we find that existing global gradient attribution met...
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
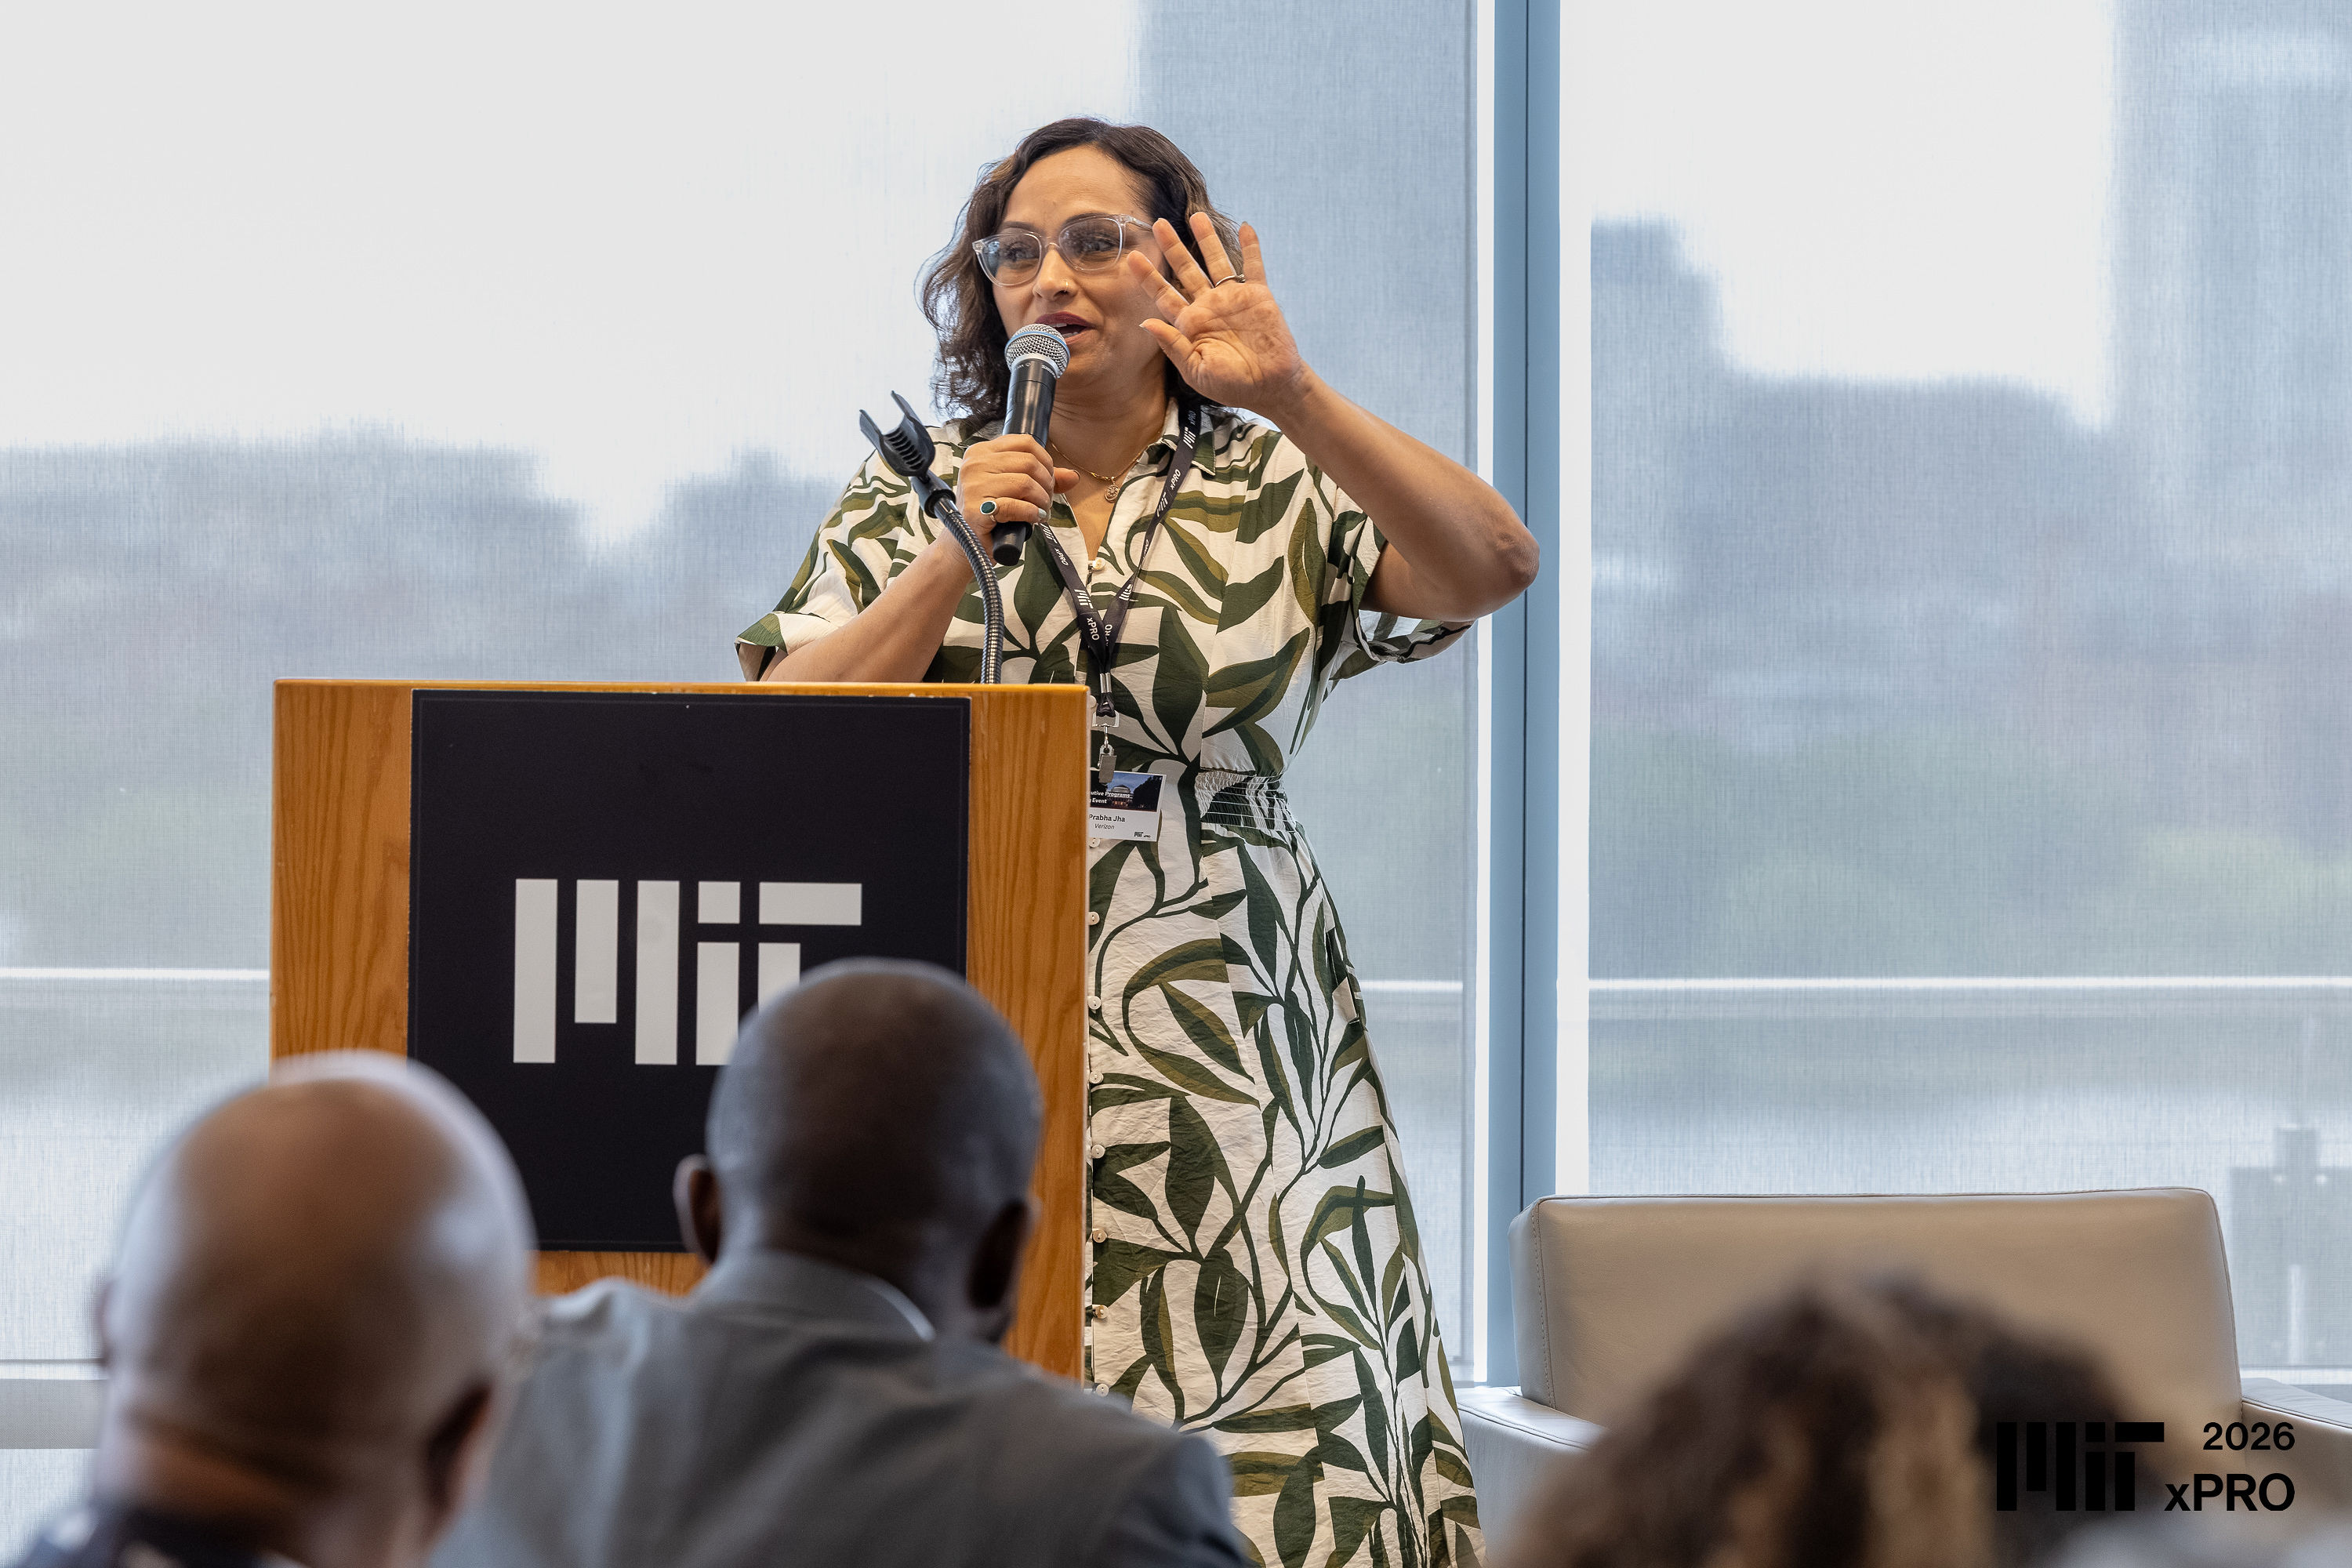
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.