Objective. A decoder of imagined speech that works for a new user without calibration would make a non-invasive speech interface practical. We tested whether imagined-speech content recorded with scalp electroencephalography (EEG) transfers across people, and examined why accuracy within a single person remains low. Ap...
Deep learning models, particularly Long Short-Term Memory networks, are increasingly used for operational streamflow forecasting, with ensemble spread providing a signal of predictive uncertainty. As climate change increases the frequency of hydroclimatic extremes, these models will increasingly operate under flow cond...
A-SLS, a learning-aware robust adaptive model predictive control (RAMPC) framework based on system-level synthesis that forecasts future parameter uncertainty and preserves correlations between process disturbances, parameter error, and estimate updates to construct tight, guaranteed reachable sets that account for fut...
This paper investigates the statistical behavior of Stochastic Gradient Descent (SGD) with constant step size under the framework of iterated random functions. Compared to previous studies establishing the convergence of SGD in probability measure, e.g., Wasserstein distance, our approach directly provides the converge...
Jia-Qi Li, Zhipeng Lou, S. Richter et al.· 8 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Learned warm starts for the simplex method build starting bases using predictions of which variables will be basic at optimality. Prior work has shown that starting bases predicted by graph neural networks can sharply reduce iteration counts, but the time saved may fall well short of the iterations saved. On 25 classes...
Felix Parker, Danielle A. Ripsman, Emmett Springer et al.· 0 citations
While foundation models and vision transformers (ViTs) have redefined visual representations, current active learning (AL) strategies for these backbones largely operate at the patch or region level, where annotation requirements remain high due to extensive pixel labeling. Extending ViT-based AL to the pixel-level, lo...
Utku Cicek, Mahipal Singh, Zi-Yao Shang et al.· 0 citations
We present a generative surrogate for charged-current \(\nu_\mu\)-nucleus scattering that can be calibrated to measured differential cross sections without event-level experimental samples. Starting from a theoretical interaction model, we fine-tune the surrogate to a MicroBooNE measurement and show that this also impr...
Jose Luis Bonilla, Krzysztof M. Graczyk, Rwik Dharmapal Banerjee et al.· 0 citations
Unsupervised speech denoising methods such as MixIT and noisy-target training can be trained directly on noisy recordings, avoiding the sim-to-real gap of synthetic training data, but remain well below supervised performance. Teacher--student self-training, as in RemixIT, narrows this gap by remixing a teacher's estima...
The Time-partitioning Gaussian Process Mixture Model (TPGPMM), a Bayesian nonparametric framework for regime identification and nonstationary prediction that infers such regimes and their within-regime dependence from data, without Markovian assumptions is proposed.
Typology-aware tokenizers are motivated by the claim that segmentation which respects morpheme boundaries preserves information that frequency-driven segmentation destroys. Studies routinely establish that it helps while assuming the boundaries must be linguistically correct. We separate them. Tagalog marks voice with...
Abdul Rehman Antall, Baidya Nath Saha· 0 citations
Understanding when neural networks learn interpretable representations is central to mechanistic interpretability. We study this through identifiability: when can supervised learning recover the true latent variables underlying the data? We introduce two data generating processes distinguished by their causal direction...
A machine-learning approach called CheMeleon provides a practical way to develop new drugs or other molecules with much less detailed, expensive experimentation.
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Learn how Google Antigravity and our Cheminformatics Skills accelerate drug discovery workflows, search compounds, and propose novel rigidified macrocycles.
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
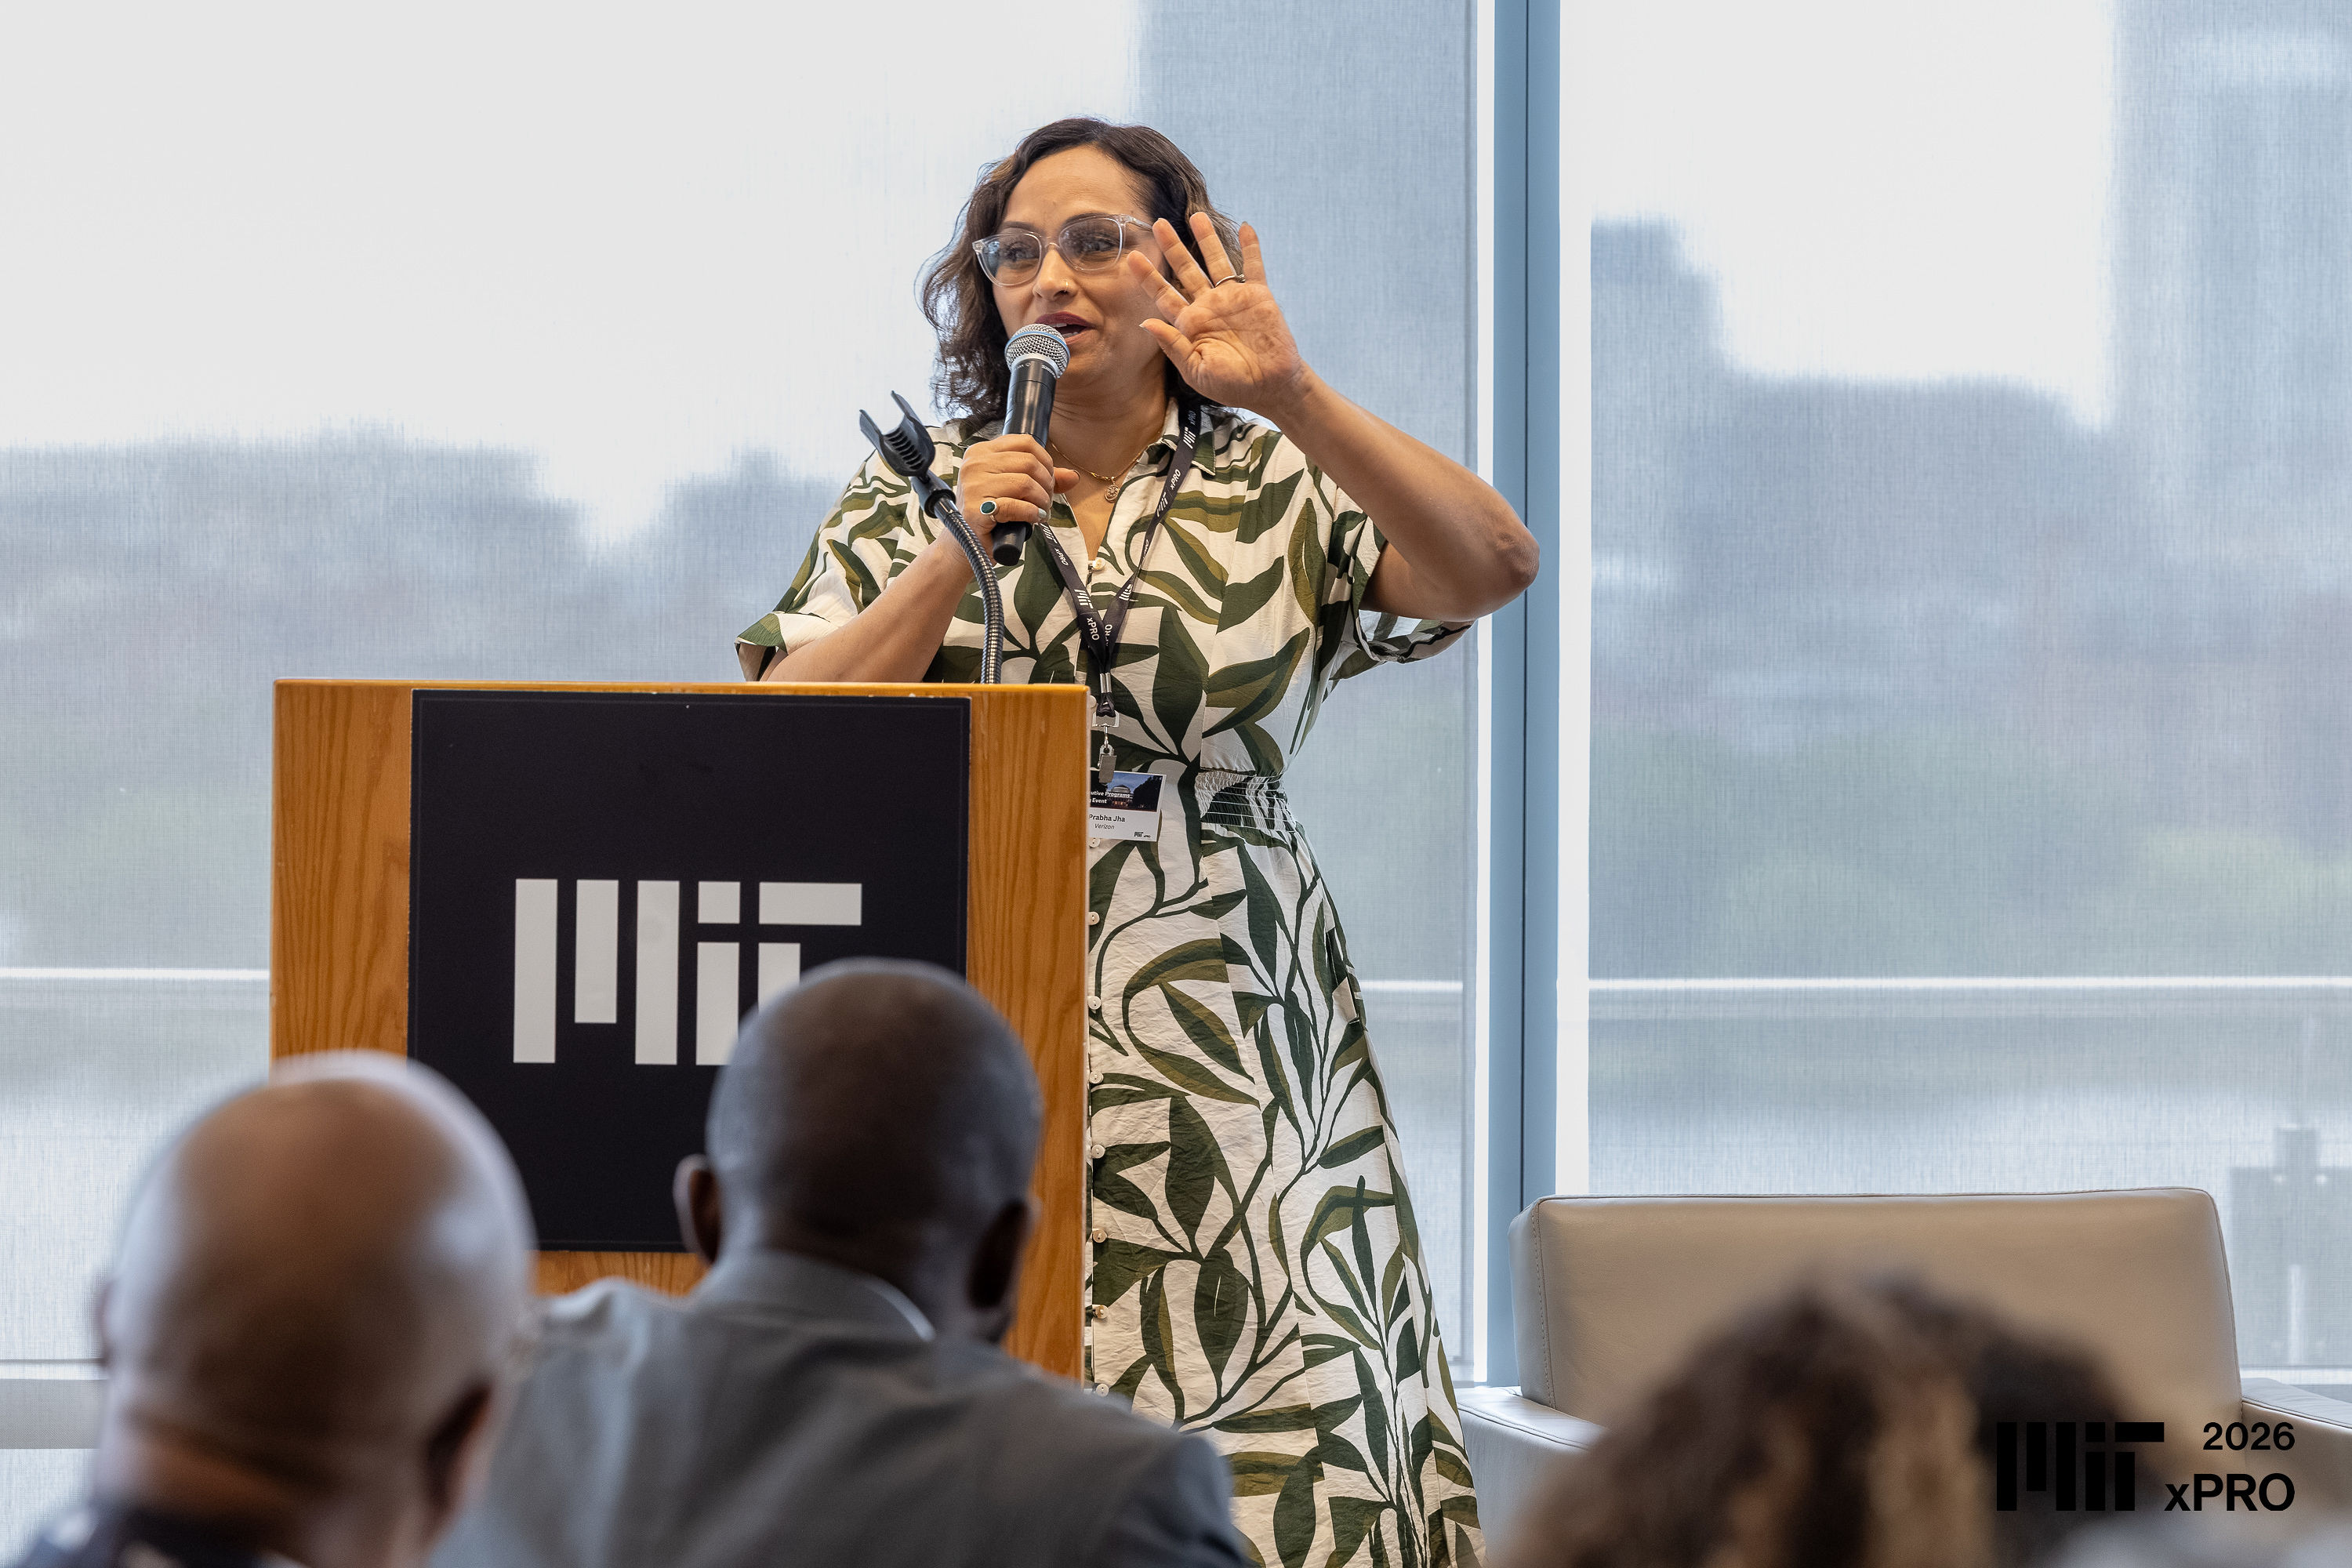
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.