This paper proposes Test-Time Correction (TTC), a hypothesis-based correction framework guided by a simple principle: hypothesize, reconstruct, correct, that consistently improves accuracy over state-of-the-art VLM-TTA methods while achieving up to 2x speedup, over 3x lower CPU memory usage, and up to 1.4x lower GPU me...
The findings identify the denoising trajectory as a new control channel in dLLMs and call for bias audits that examine the serving stack rather than the frozen model alone.
Sarim Hashmi, Mukul Ranjan, Abdelrahman W. A. Elsayed et al.· 0 citations
Language models process and generate text sequentially in token units, and the tokenizer determines how much text each inference step covers. Under standard tokenization, a short English phrase such as"On the table."is usually produced as four separate predictions for the preposition (On), article (the), noun (table),...
On-policy distillation (OPD) has emerged as an effective post-training paradigm for language models, with recent efforts extending it to block diffusion language models (BDLMs). However, existing studies focus almost exclusively on small block sizes, leaving distillation into student models with larger blocks underexpl...
Zai-Quan Yang, Fei Wei, Yong Wang et al.· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
When documents supporting an agent's derived facts are revoked or replaced, should it repair memory or re-read current evidence? We introduce an evidence-revision evaluation on medication- and problem-list tasks from public ICU records. Under revocation, replacement and control events, we compare full and source-filter...
Reinforcement learning post-training for language models relies on two reward designs: human preferences (RLHF, DPO) and binary verifiers (RLVR). Clinical question answering fits neither. Near-correct answers differ by a single substituted entity, and no executable check decides clinical correctness. We instantiate a s...
CLIP-like vision-language models remain a cornerstone of multimodal systems, yet their scores stay near chance on directed spatial relations, such as whether one object is left of another. We call this failure readout blindness and analyze, theoretically and empirically, why deployed scores miss the direction: when sco...
Guang-Yuan Li, Tian-Ming Du, Yan Jiang et al.· 0 citations
Training a small projector between a frozen vision encoder and language model is an established approach to multimodal learning. As the parameter count of language models scales dramatically, we revisit which vision capabilities this approach can add while keeping their pretrained weights fixed. Here we train a 50M par...
Jaehoon Lee, Harry B. Partridge, M. Jayasekara et al.· 0 citations
Generative large language models (LLMs) inherit undesirable behaviors from pre-training, including demographic bias and toxic generation, that often emerge only after deployment and affect a small subset of inputs. A repair should eliminate the identified defect, preserve the model's overall functionality and, ideally,...
Hsin-Ling Hsu, Min-Yue Chen, Nai-Chia Chen et al.· 0 citations
Language models increasingly serve prompts that carry private data, and secure inference under homomorphic encryption lets a client outsource the computation without revealing the prompt. Existing secure inference systems run a forward pass without consuming a token under encryption, and generating text with them requi...
Post-training quantization to the GGUF format's mixed-precision K-quants is commonly how open-weight language models reach consumer hardware, yet its effect on fine-grained lexical competence is uncharacterized. We audit 27 quantized artifacts across 13 families and four architecture backbones, 0.35B-14B parameters, ev...
Saurabh K. Singh, Yogeshwar Singh Dadwhal, Malhar Vedak· 0 citations
Every recurrence of a looped language model adds cost in training, decoding, prefill, and reinforcement learning (RL). The closer recurrent states get to fixed points, the less the path to them matters. This enables truncated backpropagation in training; terminal key-value (KV) sharing for decoding with almost no loss...
Benhao Huang, Chu-Fan Shi, Jun-Lin Chen et al.· 1 citation
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
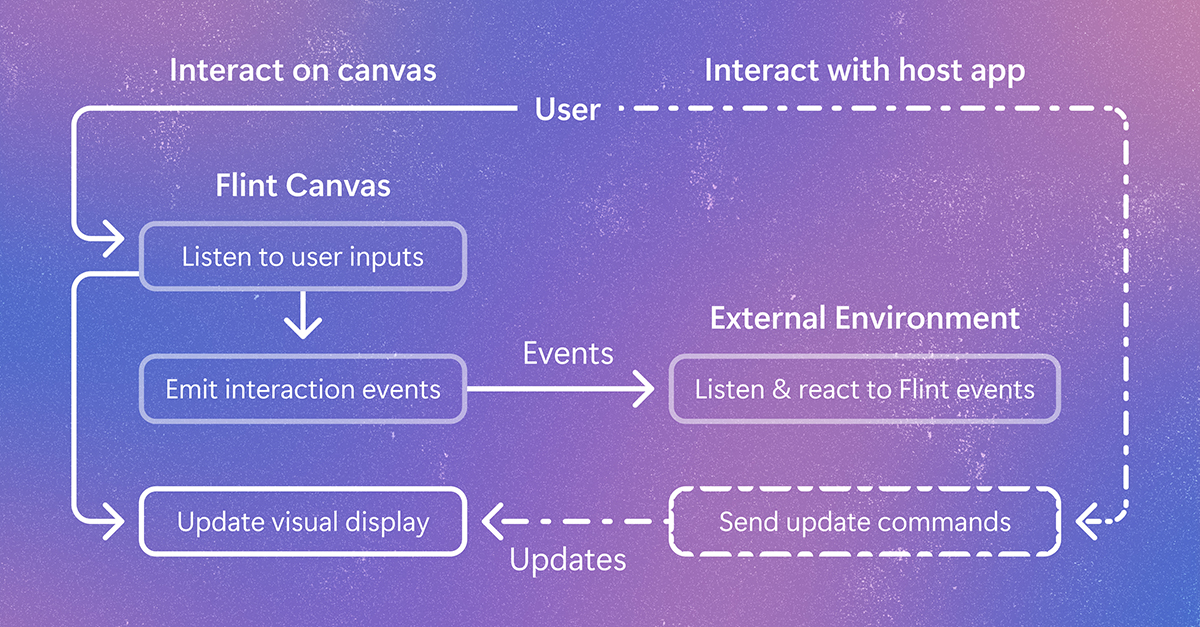
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.