This work presents QGenome, a semantic foundation for quantum software genomics that establishes a falsifiable framework and a concrete research agenda for gene mining, lineage recovery, cross-layer regression testing and repair, and evidence-grounded quantum software agents.
Jiongchi Yu, Yue Duan, Zi-Ming Zhao et al.· 0 citations
This analysis focused on their classification performance, stability, agreement with experts, top-2 candidate recovery, and multi-LLM voting workflows (S1-S4) along with a corresponding analysis on Keras.
Asli Sari, Ayse Tosun, G. Alptekin· Proceedings of the 1st Inter...· 0 citations
The experience suggests that the PromptOps practices recently proposed for general LLM applications transfer directly to security engineering, and that a fixed evaluation corpus with cost-aware metrics is the single most valuable artifact a prompt-pipeline team can maintain.
Eldar Mametov, Andrey Sadovykh, Eugene Zouev et al.· Proceedings of the 1st Inter...· 0 citations
It is concluded that developers should use LLMs at the source-code level to counter adversaries applying the same techniques on decompiled code and research should advance decompilation support for the growing language diversity in the iOS ecosystem.
Fabian Scherf, Florian Magin· Proceedings of the 2nd Inter...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Coding-agent trajectories are read as evidence about the software process, and analyses pool runs from many different tasks. The task predicts both the behaviour and the outcome, so a pooled estimate mixes a within-task and a between-task channel, and is read as a statement about runs. We quantify that mixing with the...
FitGen is presented, a validation guided repair framework combining structured prompt design with output, syntax, and semantic validation to automatically diagnose and repair executable fitness functions.
Md Al Muzahid Nayim, Faezeh Rajabi Kouchi, Amit Kumar Sikder et al.· 0 citations
This work examines three test-generation strategies that vary in coverage and emphasis on ambiguous behaviours and discusses the implications for autonomous software engineering pipelines in which a single model generates both code and tests from the same specification.
The number of exploited software vulnerabilities rises every year, and their impact grows as software systems become ever more interconnected. To detect such vulnerabilities in large codebases, many organizations rely on Static Application Security Testing (SAST) tools. However, SAST tools can produce high volumes of f...
Linus Bennin, Oshando Johnson, Eric Bodden· 0 citations
Under this model, generative components ground test intent at authoring time into reviewable artifacts, rather than re-evaluating locators during every test run, and semantic agreement is achievable but not automatic: nine of twenty guarantee-surface pairs resolve.
Simarjot Khanna· Proceedings of the 1st Inter...· 0 citations
Applying large language models (LLMs) to regulated domains such as financial and legal compliance is fundamentally a software engineering problem: an answer produced from a model’s parameters is, at the surface, indistinguishable from one grounded in the authoritative source, yet only the latter can be audited. Prior s...
Monalisha Ojha, P. Mishra· Proceedings of the 1st Inter...· 0 citations
Eight lessons from six months of developing CHERI-PIT, an LLM-agent pipeline that ports C/C++ projects to the memory-safe pure-capability (purecap) ABI of CHERI hardware on Arm Morello, trace a path toward a porting tool that emits reproducible and auditable port recipes.
Noam Benkler, Steven Johnston, D. Lide et al.· Proceedings of the 2nd Inter...· 0 citations
Parity testing validates software modernization: the legacy system supplies every expected output, so the oracle is sound. One decision is delegated, increasingly to a language model and often the very model that translated the code: which inputs to try. How much divergence such suites let through is unmeasured, and wh...
Simarjot Khanna· Proceedings of the 2nd Inter...· 0 citations
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 6, 2026
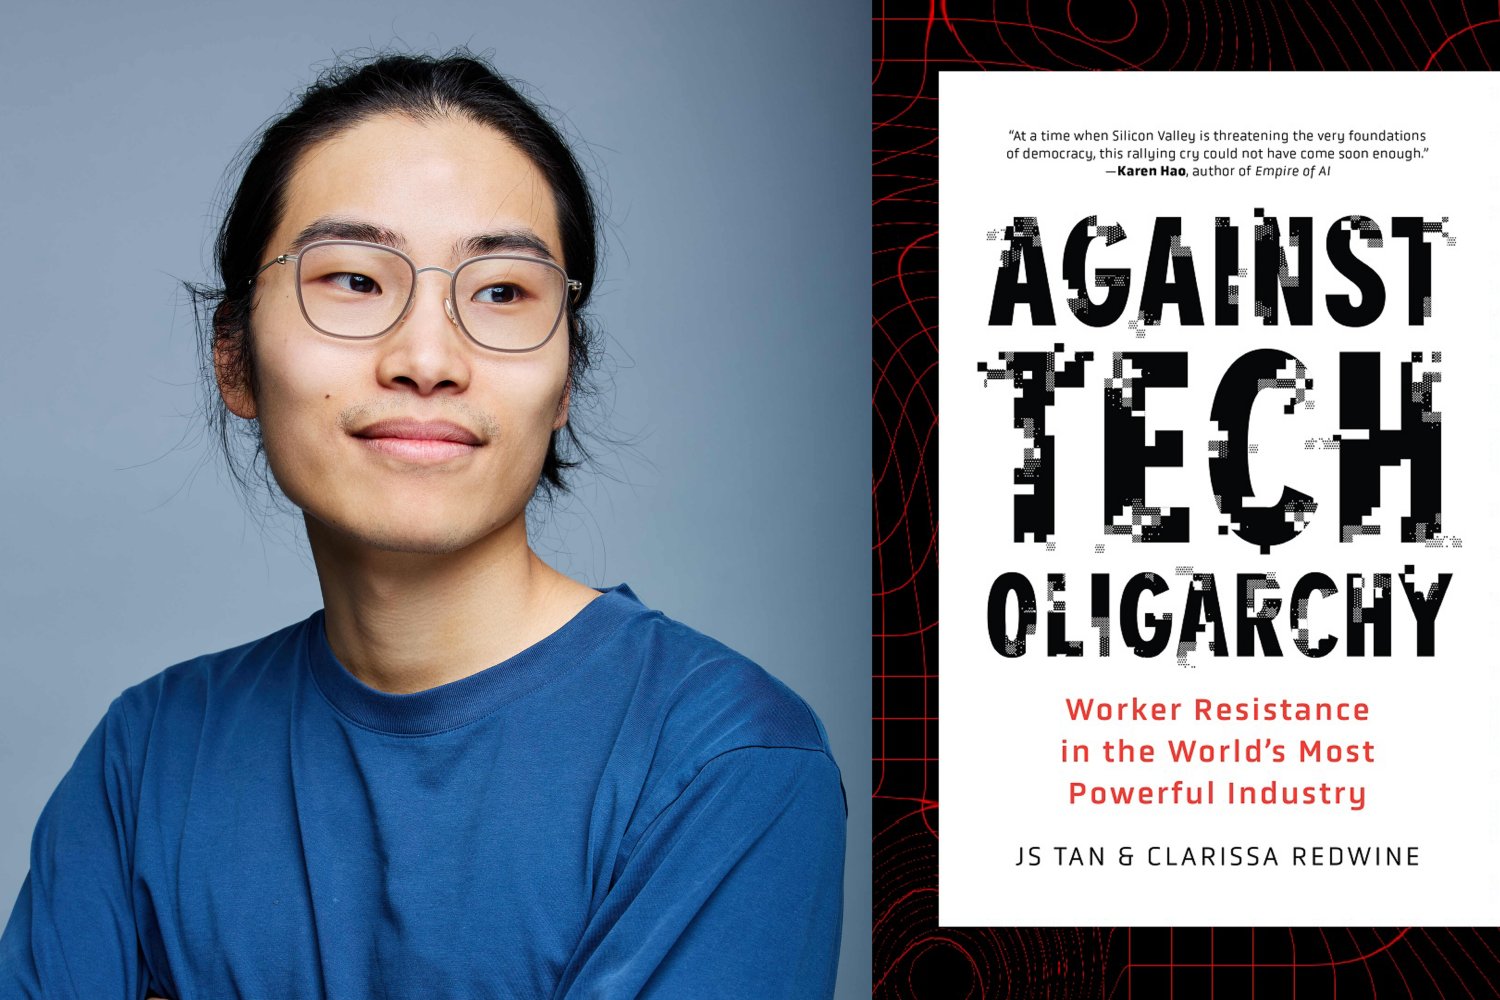
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
MIT News · Artificial Intelligence· news.mit.eduOct 2, 2026
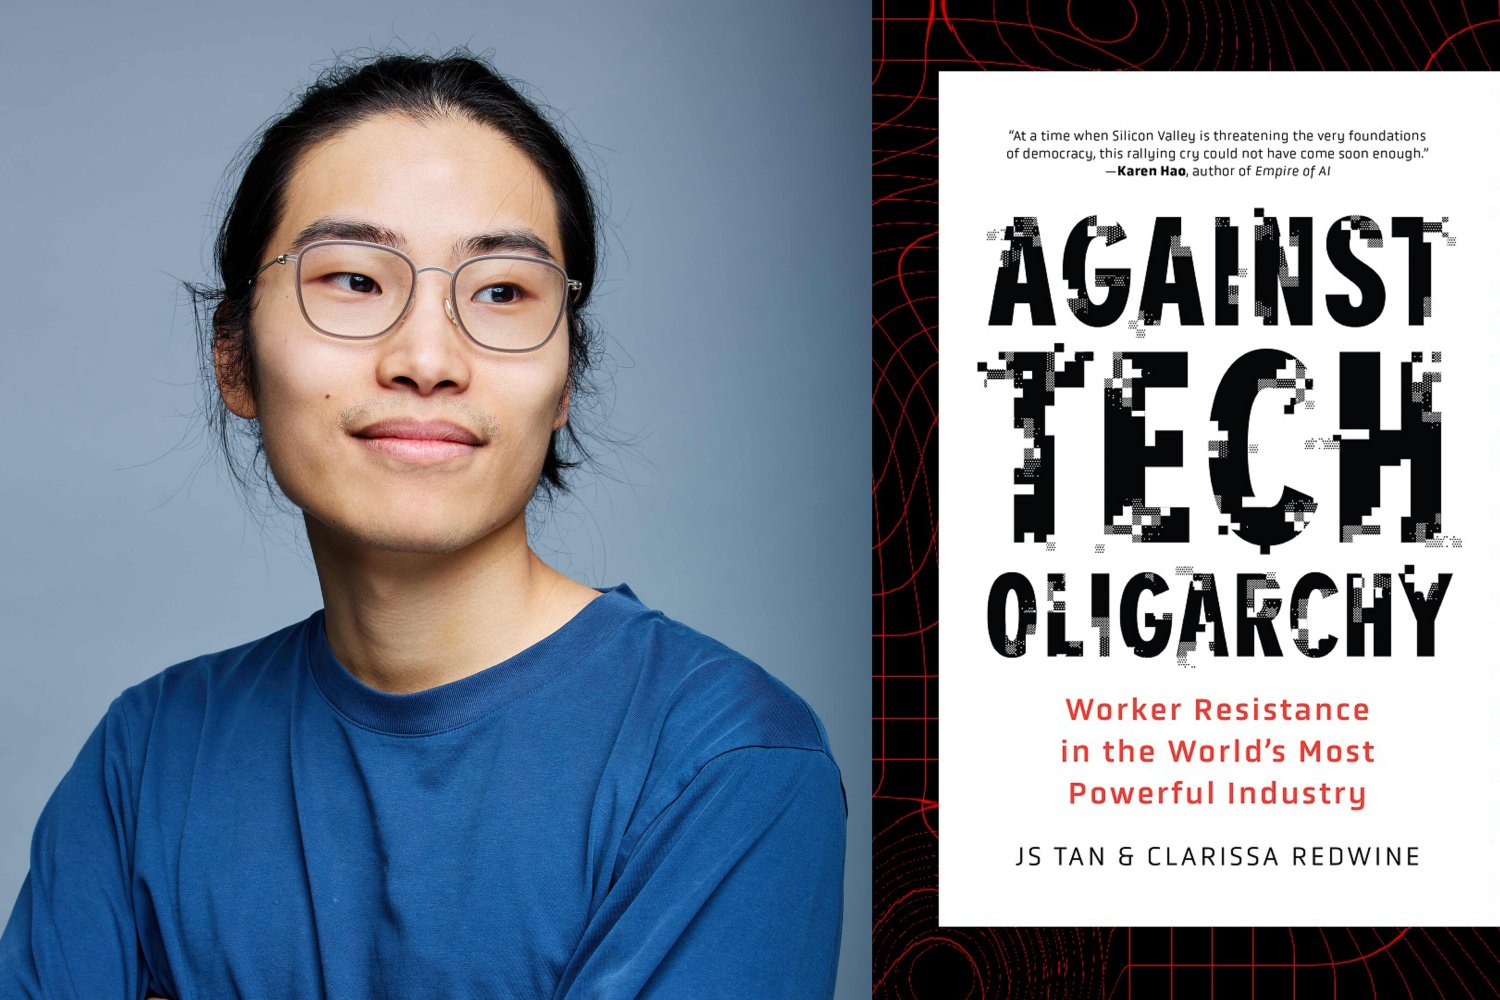
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
Requirements in large systems rarely exist in isolation. Their meaning depends on the wider project context - other requirements, policies, decisions, tests, and implementation details. That becomes especially important when AI is used for review, because spotting a possible conflict or gap is only the beginning. ReqSpace explores how AI, visualisation, and connected project context can help reviewers understand those findings, trace the relationships behind them, and focus on the questions that…
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.