This vision paper argues that trustworthy AI-assisted software engineering requires behavioural accountability: making implicit assumptions explicit, surfacing behavioural violations, and producing auditable evidence for developers and CI pipelines.
Radosław Klimek· Proceedings of the 1st Inter...· 0 citations
Viewing trustworthy automation through this governance perspective reveals two complementary governance responsibilities: Before automated execution, trustworthiness objectives must be systematically operationalised into lifecycle artefacts that guide or constrain engineering behaviour and after execution, operational...
C. Braga, Manuel A. Serrano, E. Fernández-Medina· Proceedings of the 1st Inter...· 0 citations
This paper argues that AI and program analysis are not competing technologies but complementary capabilities, and envision enterprise software engineering as a collaboration in which program analysis provides evidence, AI provides intelligence, and human engineers contribute the judgment and wisdom required to build tr...
Vini Kanvar· Proceedings of the 2nd Inter...· 0 citations
GRAML, a framework that combines graph evidence, vulnerability description generation, and multi-task training, is proposed, and practical guidance for building more reliable and secure software engineering systems with large language models is provided.
Ruo-Han Li, Miao-Qing Tian, Hai-Peng Qu et al.· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Large language models equipped with development environments have moved code generation toward repository-scale construction, yet building complete repositories remains difficult because interacting modules, interfaces, configurations, tests, and dependencies must work together. We introduce Code Primitives, agent-nati...
Hai-Bo Jin, Peng Kuang, Xu-Chen Yu et al.· 0 citations
Multiphysics continuum models are powerful tools for studying electrochemical devices, enabling in silico reactor design and resolution of local pH, potential, and concentration fields that govern device performance but are difficult to measure experimentally. However, constructing such models requires substantial nume...
Sebastian Castro, Maya Schuchert, Spencer A. McCluskey et al.· 0 citations
The evaluation of coding agents generally strives to be as realistic as possible. In our study, we collect 4,782 agent sessions of real software engineers in JetBrains IDEs, which we call Production Sessions. Since our subject is interactive agents, we study the sessions with at least three user messages (33% of the sa...
I. Slinko, Yaroslav Golubev, Sergey Titov· 0 citations
Public R analysis source accompanying the manuscript “Serum Trace-Element Categories and Reported First-Degree Family History of Malignancy: An Exploratory Analysis of the SPES Cohort.” This release contains the original MAIN, P95 and malignancy-category analytical branches; referee-requested revision modules; classifi...
Buonerba Carlo· Zenodo (CERN European Organi...· 0 citations
Disaggregated large language model serving introduces a recovery problem that spans request execution, remote key-value (KV) cache reuse, and service lifecycle management. A successful response does not by itself establish that the remote cache path has recovered. This report describes KVQuake, an external fault-inject...
Yunfei Sun· Zenodo (CERN European Organi...· 0 citations
TechLedger is a web application for discovering, researching, saving, and comparing software services. It addresses a
practical problem in technology selection: information about capabilities, releases, and pricing is spread across vendor sites, and
users must keep their own shortlist while reviewing it. The applicatio...
Vedika Shinde· International Journal for Re...· 0 citations
The rapid growth of e-commerce requires a deeper understanding of the differences in consumer responses to online transactions. This study examines whether consumer trust and online purchase decisions differ based on gender, age, monthly expenditure, and online shopping experience in smartphone purchases through e-comm...
Ida Zuniarti, Hari Gursida, Agus Setyo Pranowo· Journal of Economics Busines...· 0 citations
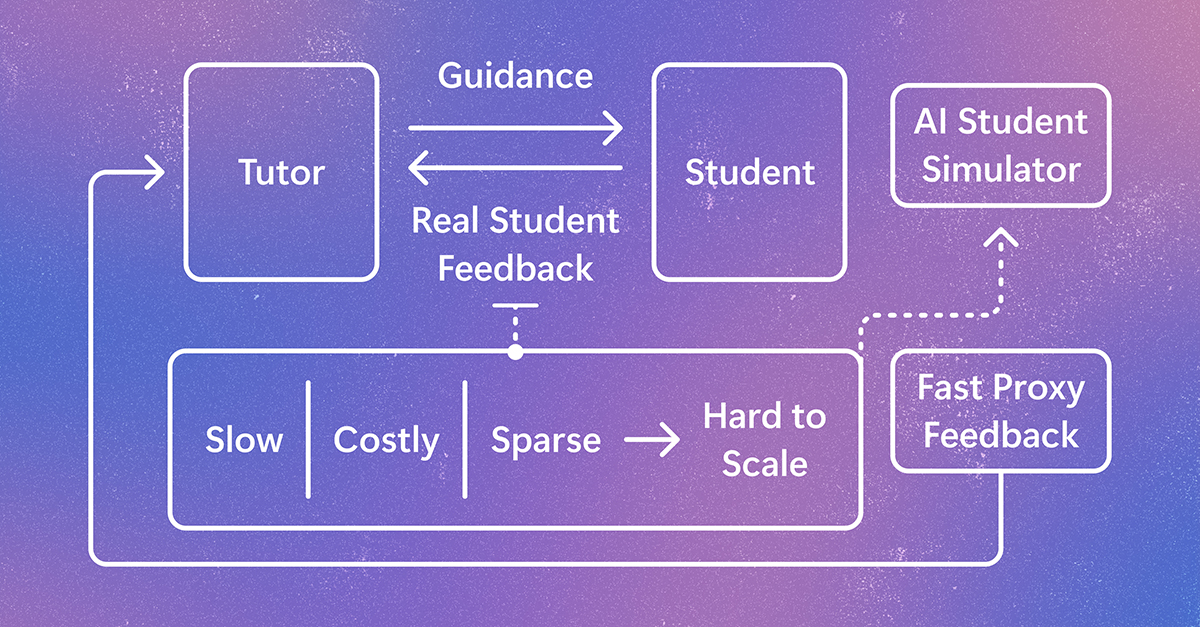
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 6, 2026
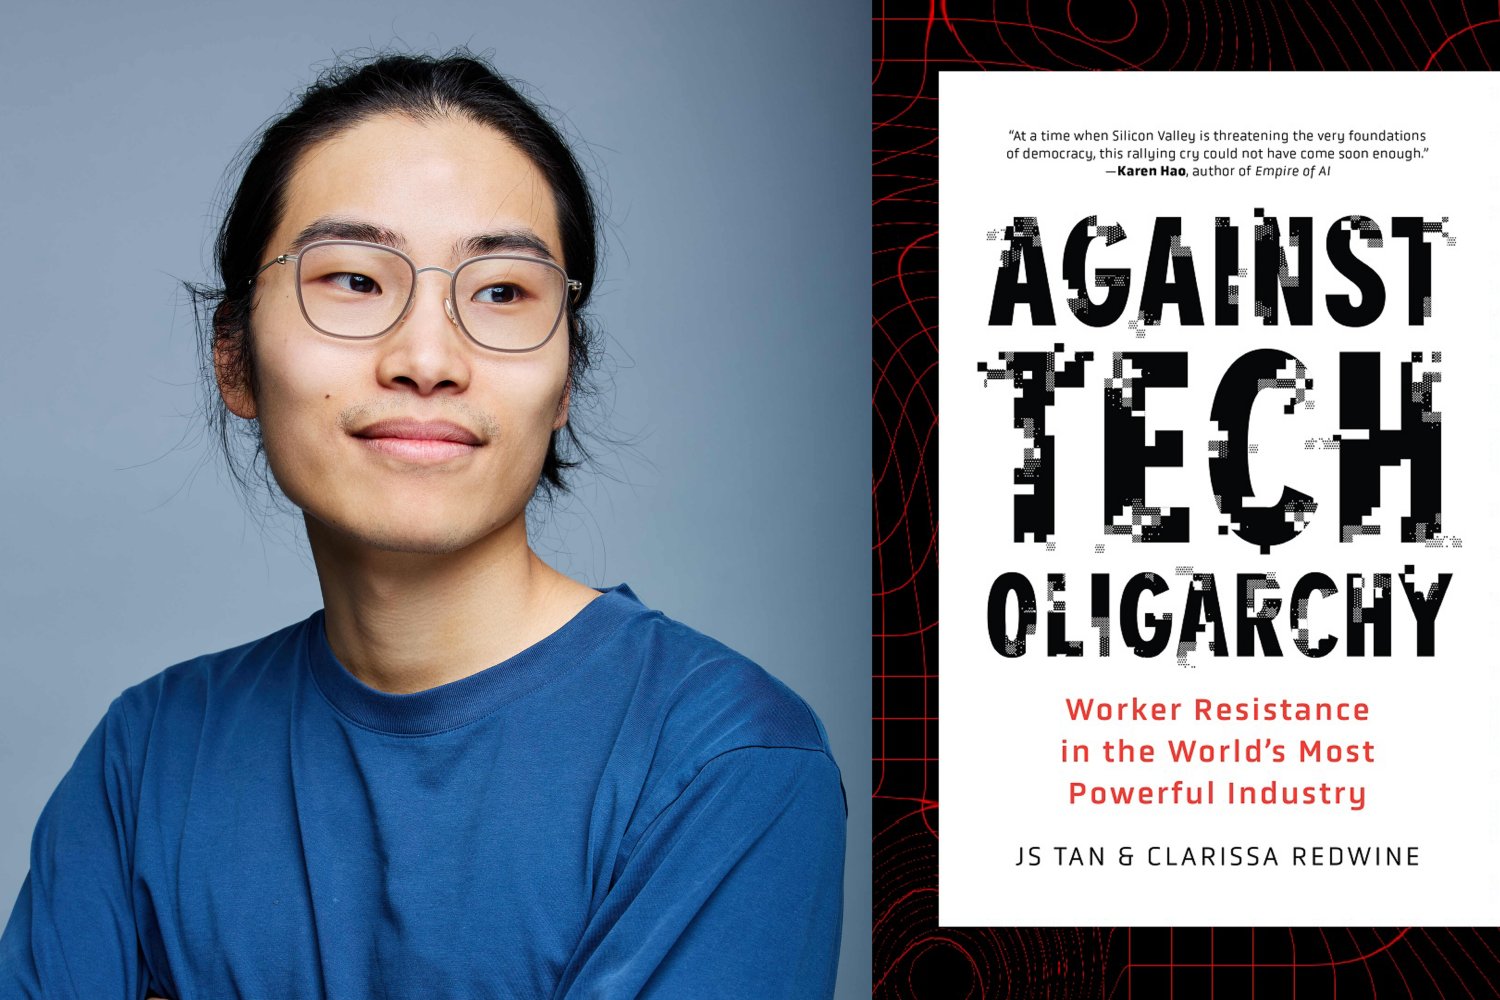
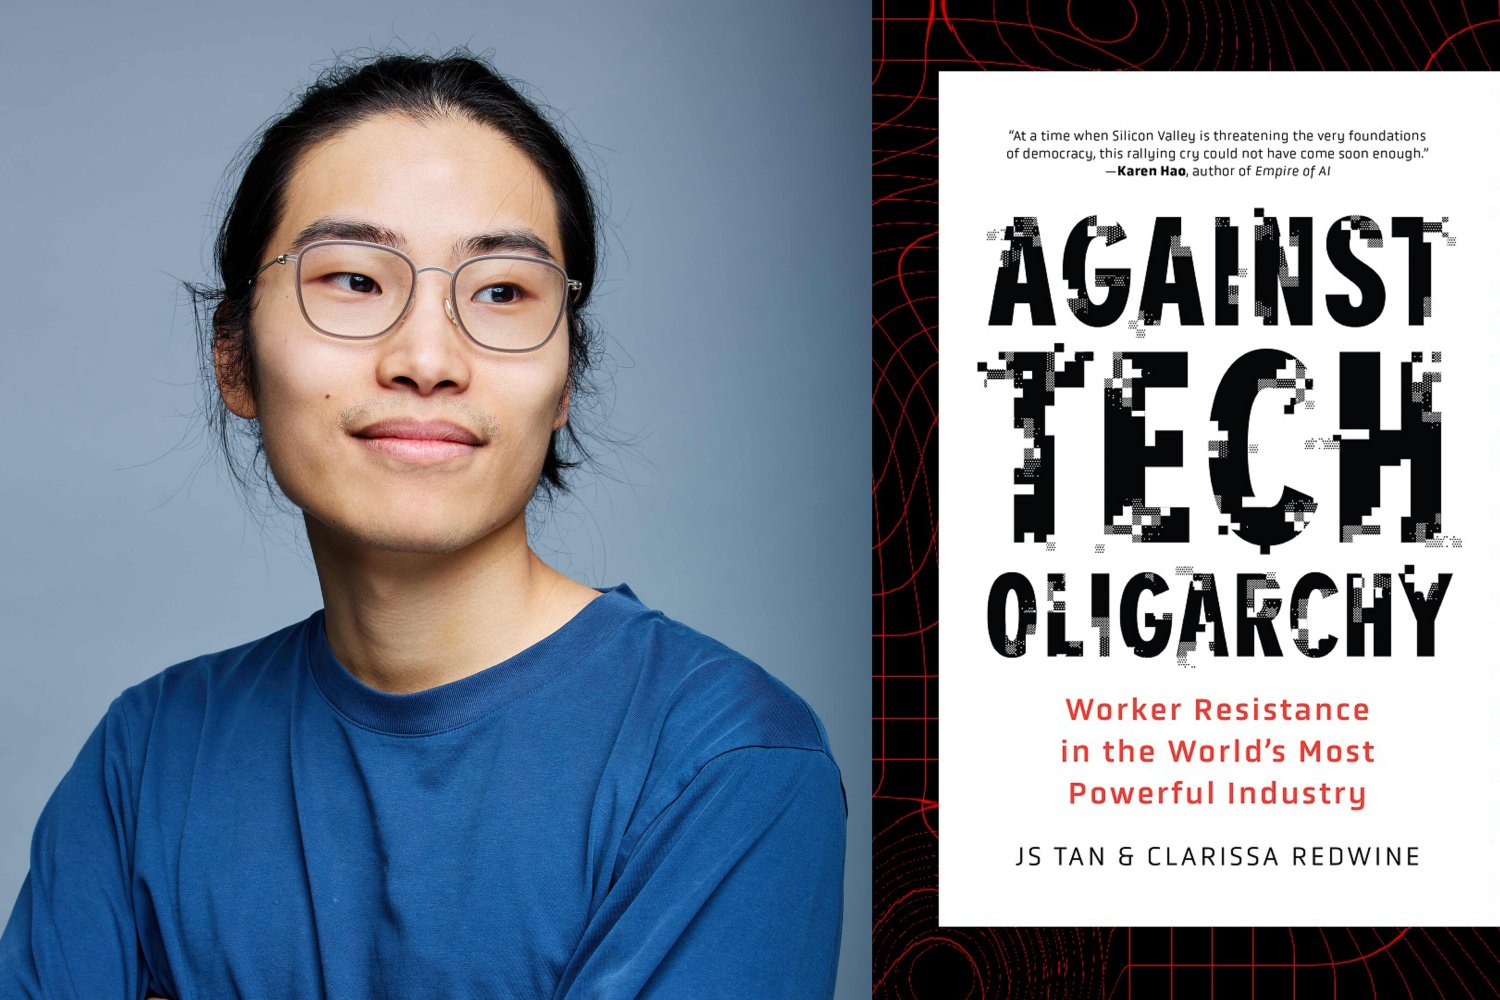
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
MIT News · Artificial Intelligence· news.mit.eduOct 2, 2026
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
Requirements in large systems rarely exist in isolation. Their meaning depends on the wider project context - other requirements, policies, decisions, tests, and implementation details. That becomes especially important when AI is used for review, because spotting a possible conflict or gap is only the beginning. ReqSpace explores how AI, visualisation, and connected project context can help reviewers understand those findings, trace the relationships behind them, and focus on the questions that…
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.