Sep 2026· Adjunct Proceedings of the 18th International Conference on Automotive User Interfaces and Interactive Vehicular Applications· 0 citations· 20 references
TL;DR
Overall, multimodal explanations appear beneficial, particularly during initial use, but should adapt to user needs and context, but should adapt to user needs and context.
Abstract
This paper investigates how different Explainable Artificial Intelligence (XAI) modality combinations affect users in fully automated vehicles across different types of ambiguous driving scenarios (ADS). In an online study (N = 123), three explanation modality combinations were compared: visual-textual (VT), visual-auditory (VA), and visual-textual-auditory (VTA). VT resulted in significantly lower situational trust and significantly higher cognitive load than VA and VTA. Explanation satisfaction increased significantly from VT to VA and was highest for VTA. While baseline levels of trust, satisfaction, and cognitive load differed between ADS categories, no significant modality–scenario interaction was found, indicating that modality effects generalize across forms of ambiguity. Based on these results, five design guidelines for XAI in fully automated vehicles were derived. Overall, multimodal explanations appear beneficial, particularly during initial use, but should adapt to user needs and context.
Explanations in automated vehicles have been proposed to support users’ understanding, trust, and acceptance of automated driving behavior. However, many explanation interfaces remain static interventions, even though users’ information needs may vary depending on driving context, familiarity, perceived criticality, an...
Philipp Asteriou, Ambika Shahu, Philipp Wintersberger· Adjunct Proceedings of the 1...· 0 citations
AMUSER is presented, a multimodal framework which simulates user behaviour and automatically generates prioritised UX improvement recommendations from resulting data and suggests an asymmetric role of multimodality: visual access during simulation improves recommendations through richer traces, while providing visual i...
Anurupa Chowdhury, Bin Wu, Hossein A. Rahmani et al.· arXiv.org· 0 citations
Results suggest that functional reliability and voice interaction quality form the primary acceptance baseline, while visual representation serves as a secondary and strategically differentiating layer for in-car conversational agents.
Esther Carolina Kaehne, Ignacio J. Alvarez· Adjunct Proceedings of the 1...· 0 citations
Current AI-based conversational agents (CAs) largely lack situational awareness, limiting their ability to understand driving context, driver state, and immediate driver needs. Consequently, the use of CA may increase drivers’ cognitive load and impair safety and user experience. This study investigates the role of sit...
Johanna Vännström, Andreas Absér, Jacob Weilandt et al.· Adjunct Proceedings of the 1...· 0 citations
HACoD is proposed, a Human–Agent Emotional Co-Driving Framework that links driver emotional needs, human–agent collaboration patterns, and affective agent design elements and highlights the need for transparent data boundaries and real-world validation.
Wei Gong, Ming-Yuan Zhang, Mei-Cheng Liu et al.· Proceedings of the 18th Inte...· 0 citations
At ICSOB 2026 in Gothenburg, we presented TenderIntell, our work on multi-agent support for tendering. This post looks back at the conference, the idea behind a panel of three AI reviewers who score each proposal independently, and why evaluating agents reliably is the question we keep coming back to. The post TenderIntell at ICSOB 2026: Three Days in Gothenburg appeared first on GPT-Lab.
MIT News · Artificial Intelligence· news.mit.eduNov 13, 2026
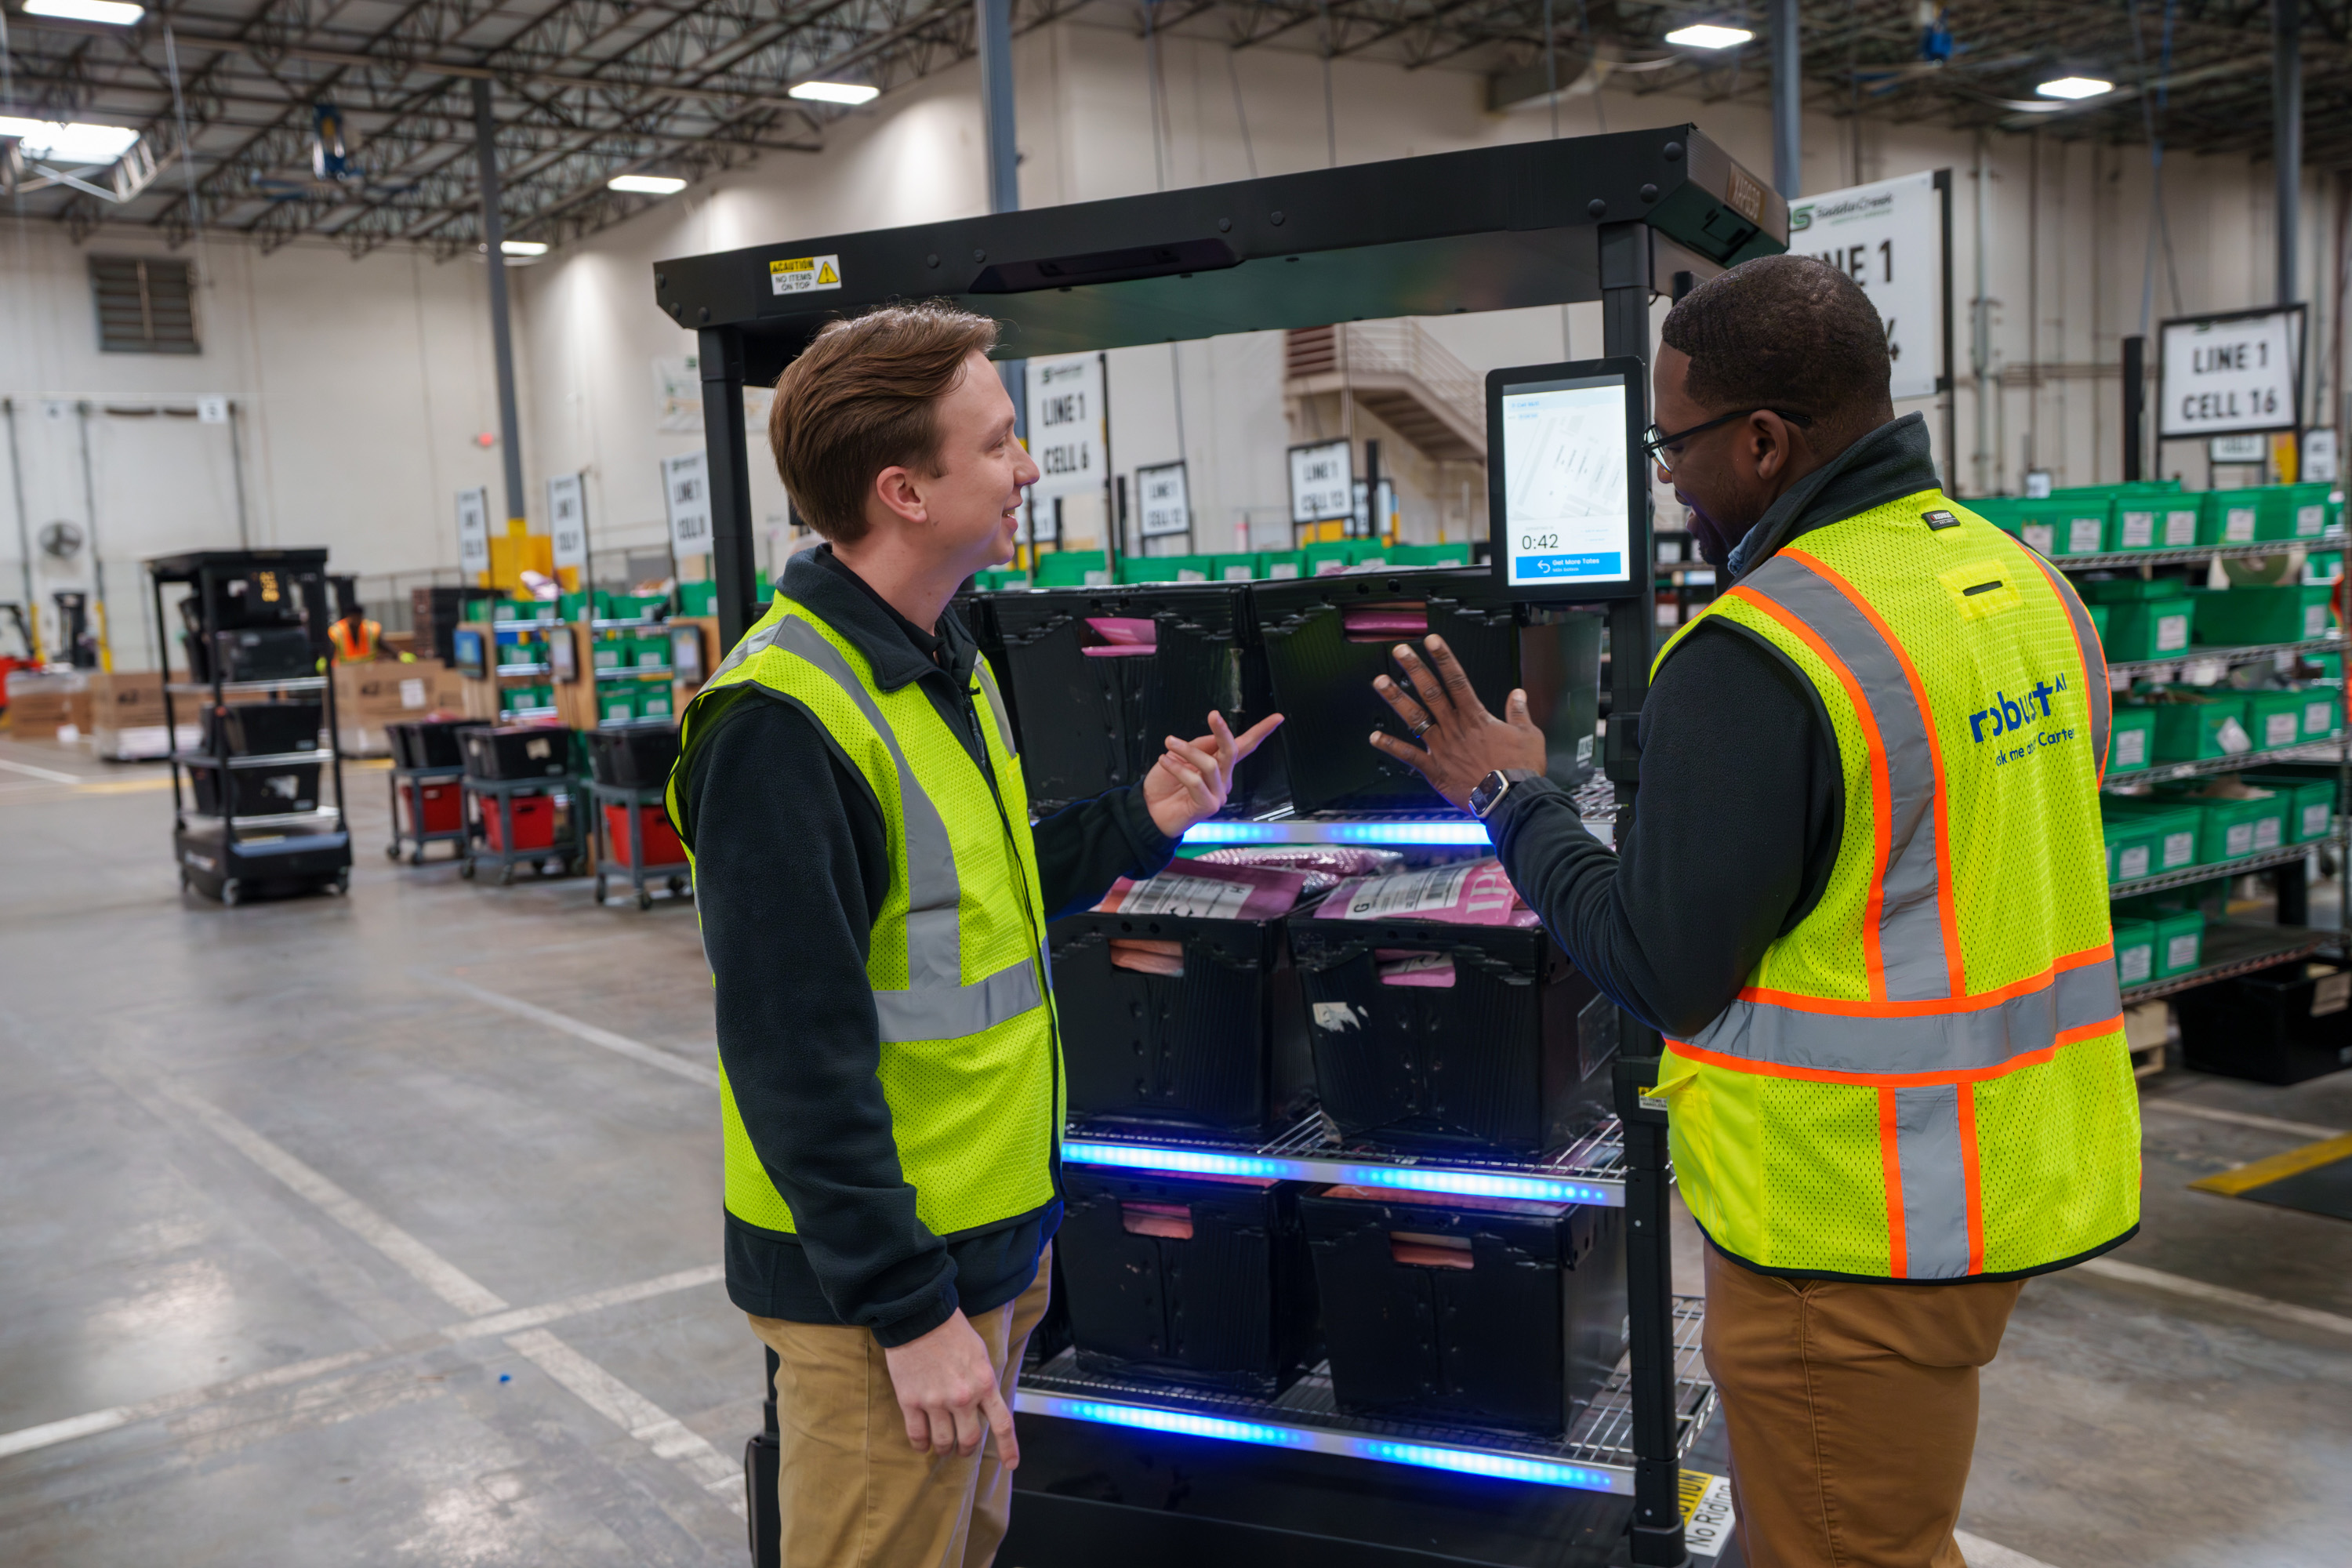
Founded by Anthony Jules ’92, SM ’92 and Professor Emeritus Rodney Brooks, Robust AI’s robots are designed to collaborate with humans in factories and warehouses.
MIT News · Artificial Intelligence· news.mit.eduNov 13, 2026