Ensuring the correctness of LLM-generated code is a core challenge for modern software engineering. Benchmarks for agentic code generation check correctness with held-out test suites, which are inherently incomplete and increasingly susceptible to memorization. Formal verification avoids both problems, but existing work covers only standalone tasks whose specifications are given as input, not real issues, which touch large repositories and state intent in vague natural language. We present Benchproofer, a pipeline that turns a coding task with a known correct patch into a formally verified one: it writes a specification for the new code, summarizes the existing functions that code calls with axioms, and admits an instance only after mechanical and adversarial gates agree. Applying it to SWE-bench Verified yields SWE-Proof, 500 real issues whose correctness is formally verified rather than tested, and it extends to SWE-bench Pro. Across two frontier models, verification catches what tests miss: a quarter to a half of test-passing patches admit counterexamples, which a structured natural-language specification does not fix, while a correct formal one lifts resolution from 85% to 95% for Opus 4.8. Writing that specification is the hard part: models that must write their own gain nothing over an unaided baseline, and only 62% of their specifications pass our audit. The usual failure is faithfulness, a specification that constrains part of the required behavior and leaves the rest free. Specification quality still tracks the outcome, failing on 89% of unresolved instances against 47% of resolved ones, making faithful specification synthesis a concrete open problem.

This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.
F. Xia, Amir Zamir, Zhi-Yang He et al.· 2018 IEEE/CVF Conference on...· 1,069 citations· ⚡112
This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.
P. Abrahamsson, O. Salo, Jussi Ronkainen et al.· arXiv.org· 727 citations· ⚡54
The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.
M. Pikkarainen, Jukka Haikara, O. Salo et al.· Empirical Software Engineeri...· 401 citations· ⚡48
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 13, 2026
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
Microsoft Research Blog· microsoft.comOct 12, 2026
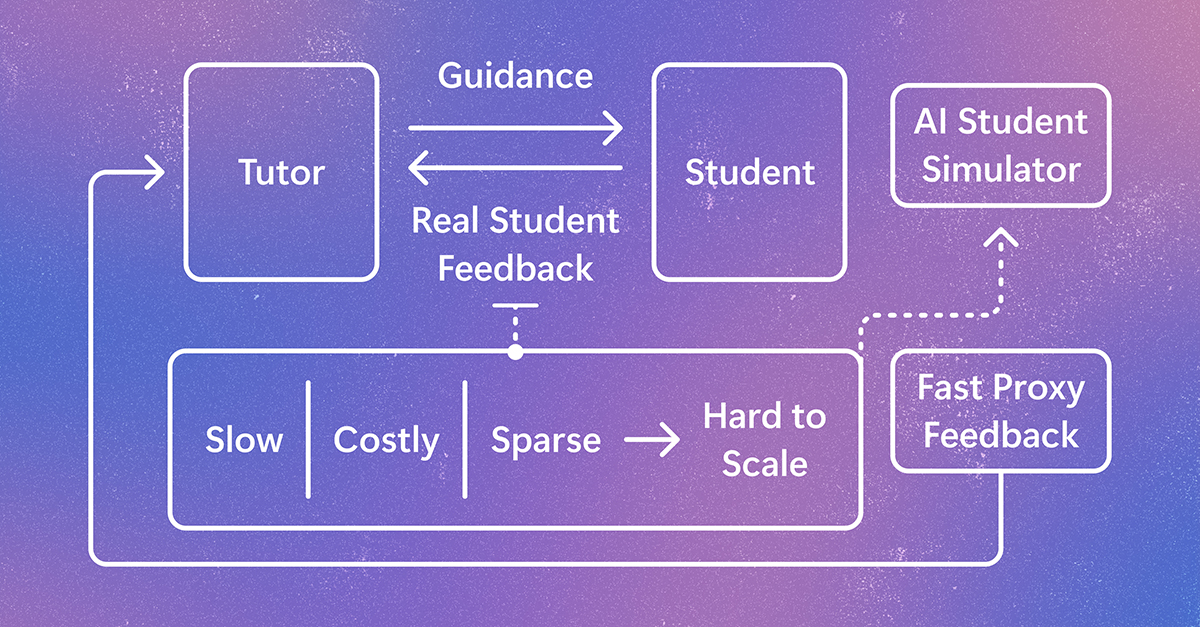
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduSep 29, 2026
Professor Sherry Turkle’s new book, “Artificial Intimacy,” offers a withering critique of chatbots and the antisocial dynamics she believes they encourage.