Background/Objectives: Pancreatic ductal adenocarcinoma (PDAC) has exceptionally high mortality, largely because of late diagnosis, while established blood biomarkers such as CA19-9 have limited sensitivity for early detection. We evaluated whether modelling serum proteomic measurements as supervised pairwise statistical graphs using synolitic graph neural networks (SGNNs) could provide a useful framework for pre-diagnostic PDAC classification. Methods: We analysed 217 pre-diagnostic serum samples from UKCTOCS, comprising 100 PDAC samples from 75 women and 117 control samples, profiled for 97 proteins. Samples were divided into a development set collected 0–1 year before diagnosis (n = 110) and a temporal holdout set collected 1–2 years before diagnosis (n = 107); 25 PDAC participants contributed samples to both windows. The final SGNN used fold-internal mutual-information selection of 30 proteins, pairwise RBF-SVM-derived edge information, minimum-connected sparsification, and a 10-member GATv2 ensemble per cross-validation fold. Conventional machine-learning comparators were tuned using development data only. Results: The SGNN achieved a mean 5-fold development ROC-AUC of 75.33 ± 10.43%, lower than the tuned Random Forest (81.67%); the other tuned comparators achieved 77.67% (XGBoost), 77.17% (logistic regression), and 73.17% (SVM). Averaging predictions across the five-fold-specific SGNN ensembles yielded a temporal-holdout ROC-AUC of 64.35% (95% CI 52.6–74.6%). In the participant-independent subset of 25 PDAC cases not represented in development and 57 controls, ROC-AUC was 66.04% (95% CI 52.56–78.88%). Conclusions: SGNNs provide a feasible graph-based representation of pre-diagnostic proteomic data but did not outperform optimised conventional machine-learning methods within development cross-validation. The temporal and participant-independent performance estimates warrant further investigation in larger fully independent cohorts. A graph-specific predictive advantage was not directly tested—no such advantage was demonstrated in this dataset—and the clinical utility has not been established.

The comparison of adopter and non-adopter sample reveals three potential adoption inhibitor, security, data privacy, and portability, which underlines the importance of the technical and security perspectives for research investigating the adoption of technology.
Nattakarn Phaphoom, Xiaofeng Wang, S. Samuel et al.· Journal of Systems and Softw...· 111 citations· ⚡8
This study investigates how Lean internal startup facilitates software product innovation in large companies and identifies its enablers and inhibitors, and shows the potential of the method-in-action framework to investigate the Lean startup approach in non-startup context.
Henry Edison, Nina M. Smørsgård, Xiaofeng Wang et al.· Journal of Systems and Softw...· 78 citations· ⚡6
Agile methods continue to gain popularity. In particular, the Scrum method appears to be on the verge of becoming a de-facto standard in the industry, leading the so called Agile movement. While there are success stories and recommendations, there is little scientifically valid evidence of the challenges in the adoptio...
A. Marchenko, P. Abrahamsson· Agile Conference· 59 citations· ⚡11
This paper highlights the challenges to conduct proper affect-related studies with psychology, provides a comprehensive literature review in affect theory, and proposes guidelines for conducting psychoempirical software engineering.
D. Graziotin, Xiaofeng Wang, P. Abrahamsson· SSE@SIGSOFT FSE· 56 citations· ⚡4
This study conducts a multiple case study on twenty European software startups and proposes a prototype-centric learning model in early stage software startups, and identifies factors that occur as barriers but also facilitators for prototyping in earlystage software startups.
Anh Nguyen-Duc, Xiaofeng Wang, P. Abrahamsson· International Conference on...· 44 citations· ⚡5
It is demonstrated that linker-free PROTACs can outperform traditional designs, marking a paradigm shift in PROTAC development for targeted protein degradation.
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
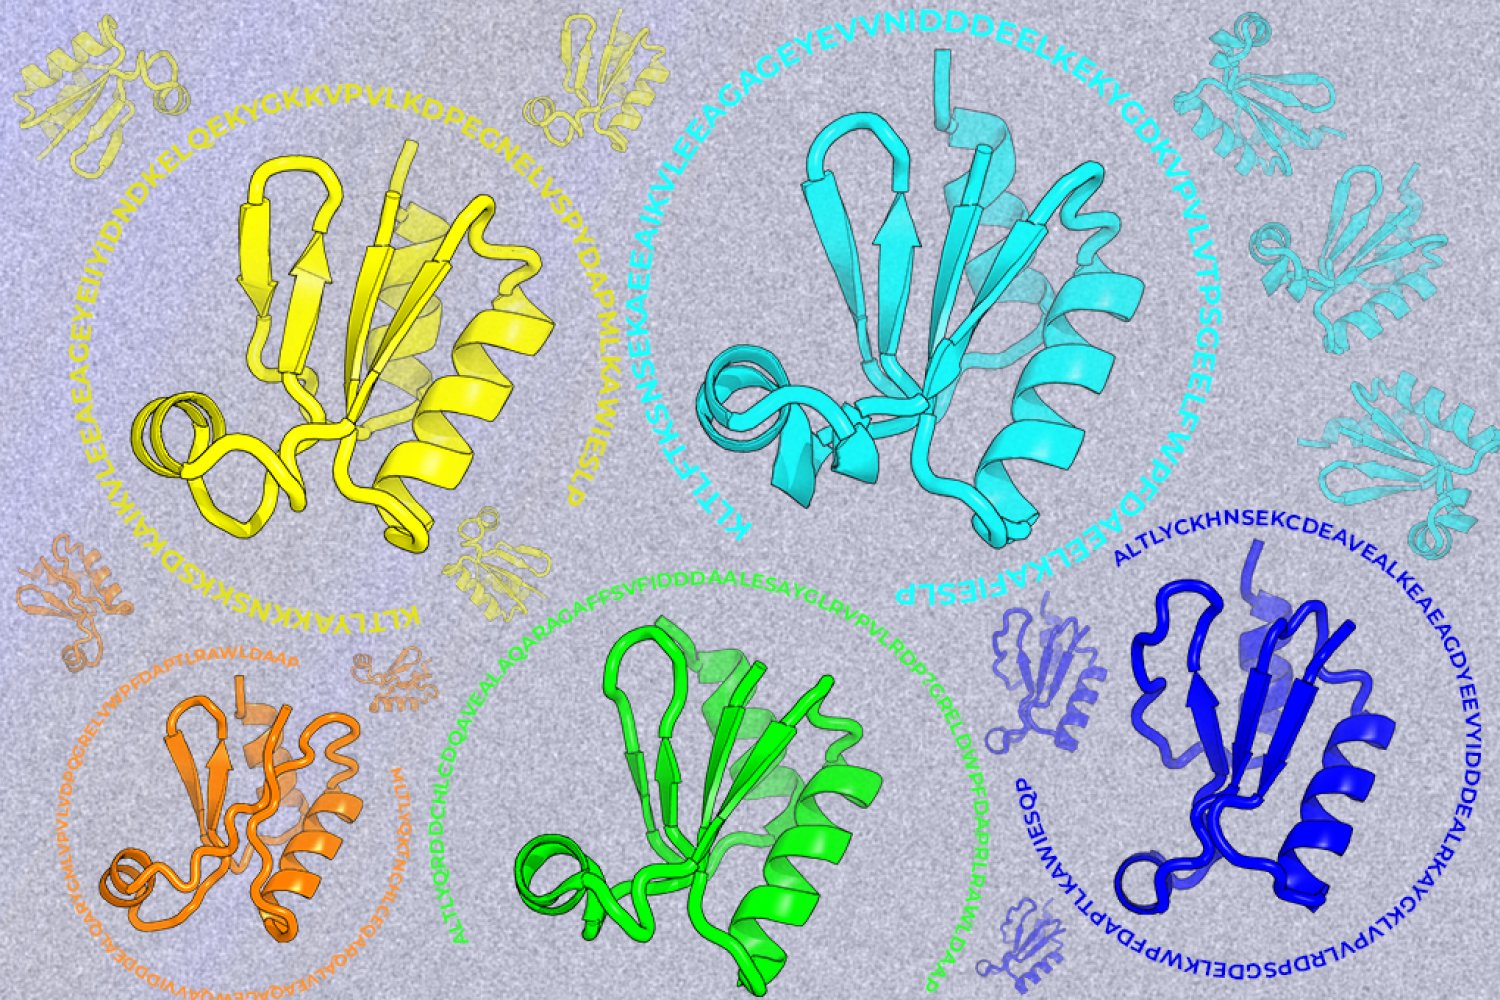
A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.
MIT News · Artificial Intelligence· news.mit.eduJul 15, 2026
Assistant Professor Pat Pataranutaporn describes a new interface that lets everyday users glimpse inside an AI's neural network before their chatbot ever says a word.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.