Skip to content
#protein folding Dataset Open access

ProDiPA: Offline Multi-Teacher Distillation and Pareto Alignment for Protein Generation

Oct 2026 · Zenodo (CERN European Organization for Nuclear Research)
Protein Structure and Dynamics

Abstract

Overview. This Zenodo record is the compact public-release view of the UniRef50-MultiProp (U50-MP) dataset: a homology-partitioned protein sequence collection with predicted structural confidence, solubility, and thermophilic propensity annotations. It does not rebuild, re-filter, re-cluster, re-split, or re-score any sequence. Dataset naming. UniRef50-MultiProp (U50-MP): the complete data resource.U50-MP15: 15,000 Train sequences with ESMFold, Protein-Sol, and TemBERTureCLS predictions.U50-FT25: 25,000 Train sequences with Fold and Thermo predictions; Sol covers only the nested 15K.U50-PP41: 40,998 strict Pareto preference pairs, including 32,930 development pairs and 8,068 evaluation pairs. Cohorts. train_15k_complete.tsv.gz (U50-MP15): 15,000 Train sequences with ESMFold, Protein-Sol, and TemBERTureCLS predictions.train_25k_fold_thermo.tsv.gz (U50-FT25): the nested 25,000-sequence Train cohort. All records have Fold and Thermo predictions; only the original 15k has Protein-Sol. The other 10k uses NA and has_sol=FALSE, not a low score.validation_1000_complete.tsv.gz: 1,000 independent Validation sequences with all three predictions.train.fasta.gz, validation.fasta.gz, test_h.fasta.gz: complete frozen sequence splits.split_membership.tsv.gz: split and homology-group membership for all 59,178 sequences.teacher_train_membership.tsv.gz: membership of the frozen Fold/Sol/Thermo teacher exports.pareto_preferences.tsv.gz (U50-PP41): strict, length-matched, role-capped Pareto preference dataset. It is suitable for unconditional preference analysis only because the 15k lacks verified four-superfamily condition labels. Provenance and interpretation. Sequences originate from UniRef50 release 2026_03 (CC BY 4.0 according to the frozen source manifest). The frozen split contains 47,342 Train, 5,918 Validation, and 5,918 Test-H sequences. Homology isolation means passing the executed project protocol; it is not proof against every remote homolog or pretrained-model overlap. All property values are computational predictions, not experimental measurements. Mean pLDDT is structural confidence, Protein-Sol is a predicted solubility score, and TemBERTureCLS is a thermophilicity classifier score rather than measured melting temperature. Test-H has no property labels in this release and was not used for teacher selection. Teacher-selection thresholds (80 / 0.60 / 0.40) are not applied to the general 15k/25k release tables. Use teacher_train_membership.tsv.gz for the actual frozen teacher subsets. Missing values are serialized as NA and must not be imputed as zero. See DATA_DICTIONARY.tsv and RELEASE_SUMMARY.tsv. License. This dataset is released under the Creative Commons Attribution 4.0 International License (CC BY 4.0).
View source

Similar papers

#computer vision Review Open access May 2015

A survey study on major technical barriers affecting the decision to adopt cloud services

The comparison of adopter and non-adopter sample reveals three potential adoption inhibitor, security, data privacy, and portability, which underlines the importance of the technical and security perspectives for research investigating the adoption of technology.

Nattakarn Phaphoom, Xiaofeng Wang, S. Samuel et al. · 111 citations · ⚡8
#computer vision Open access Feb 2018

Lean Internal Startups for Software Product Innovation in Large Companies: Enablers and Inhibitors

This study investigates how Lean internal startup facilitates software product innovation in large companies and identifies its enablers and inhibitors, and shows the potential of the method-in-action framework to investigate the Lean startup approach in non-startup context.

Henry Edison, Nina M. Smørsgård, Xiaofeng Wang et al. · 78 citations · ⚡6
#computer vision Book Open access Jul 2015

Understanding the affect of developers: theoretical background and guidelines for psychoempirical software engineering

This paper highlights the challenges to conduct proper affect-related studies with psychology, provides a comprehensive literature review in affect theory, and proposes guidelines for conducting psychoempirical software engineering.

D. Graziotin, Xiaofeng Wang, P. Abrahamsson · 56 citations · ⚡4
#machine learning Open access May 2017

What Influences the Speed of Prototyping? An Empirical Investigation of Twenty Software Startups

This study conducts a multiple case study on twenty European software startups and proposes a prototype-centric learning model in early stage software startups, and identifies factors that occur as barriers but also facilitators for prototyping in earlystage software startups.

Anh Nguyen-Duc, Xiaofeng Wang, P. Abrahamsson · 44 citations · ⚡5
#protein folding Open access Sep 2026

Programmable design of functional proteins from natural language

Pinal, a 16-billion-parameter foundation model that produces protein candidates from natural-language functional descriptions, supports natural language as a high-level interface for candidate generation in protein design, enabling programmable exploration with reduced reliance on manually specified structural or seque...

Fengyuan Dai, Shiyang You, Yudian Zhu et al. · 31 citations · ⚡3

Related blog posts

Google DeepMind Blog Sep 30, 2026

Introducing SynthID Bio

Proof of concept for watermarking AI-generated proteins while preserving biological function.

MIT News · Artificial Intelligence Aug 27, 2026

Looking beyond natural sequences

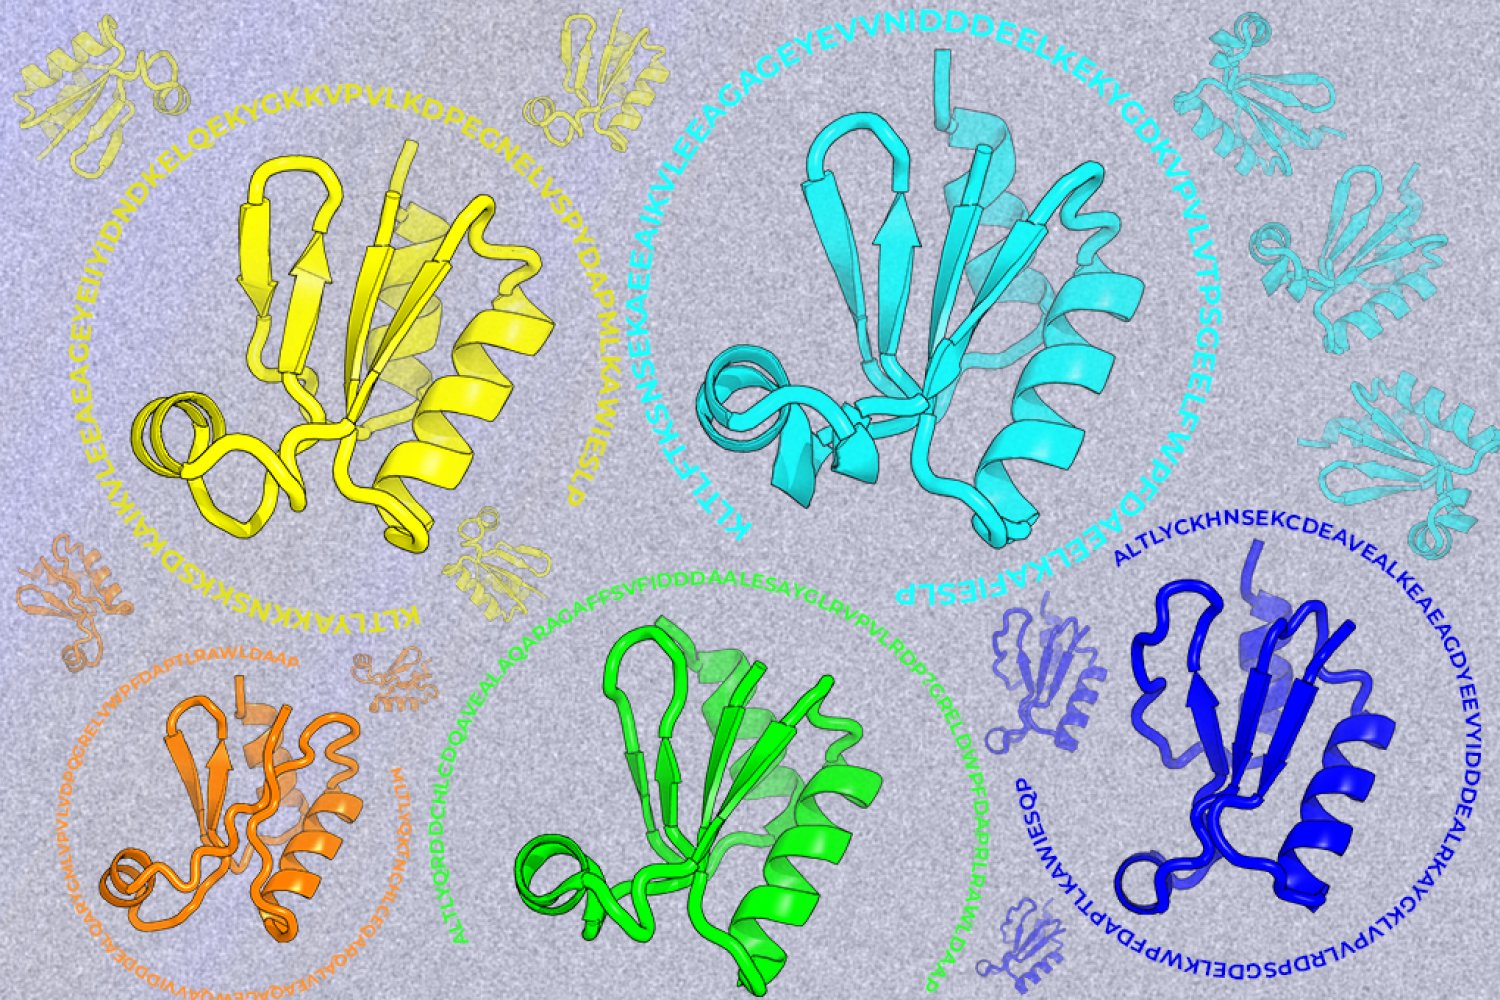
A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.